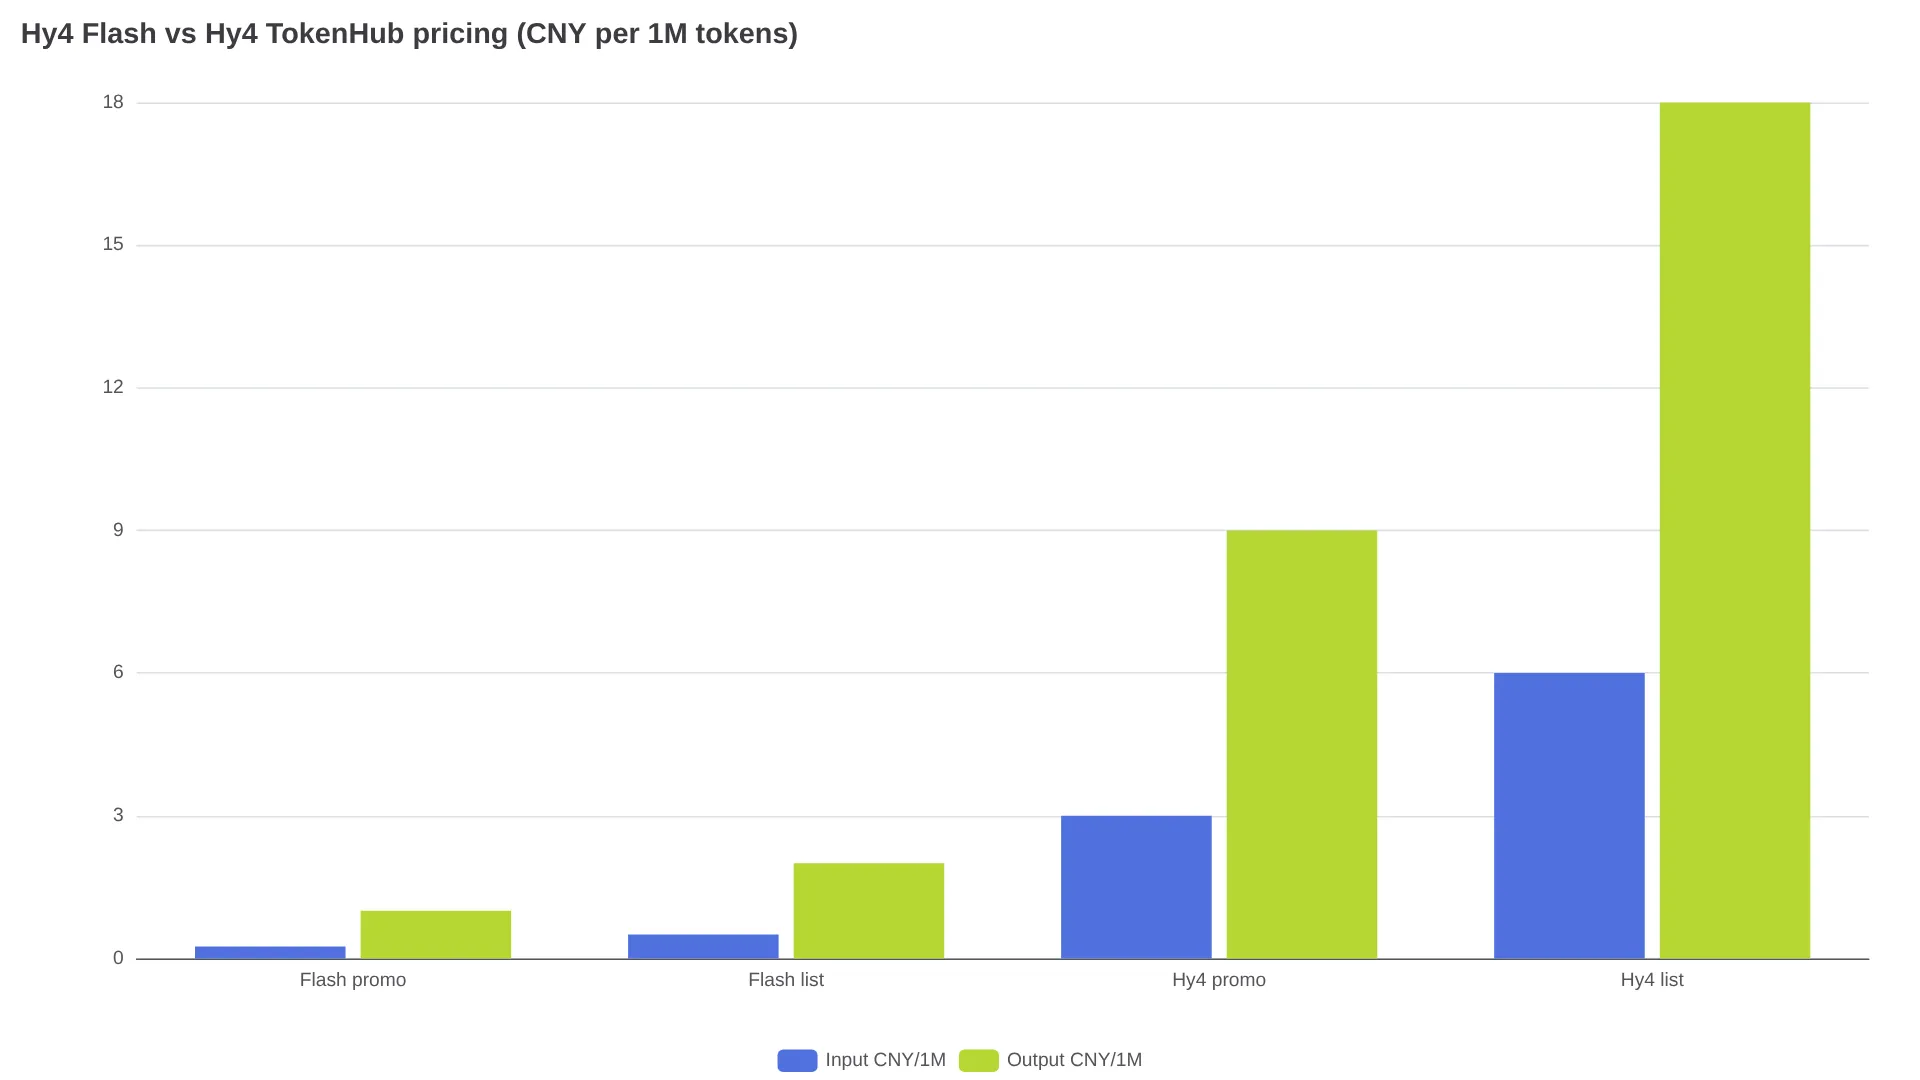
Tencent's Hy4 Flash (224B total / 12B active, 1M context) is live as of November 16, 2026. Standard rate is CNY 0.50 input / CNY 2.00 output per million tokens ($0.070 / $0.281); the current 50% TokenHub launch rate is CNY 0.25 / CNY 1.00 through November 30 at noon Beijing time.
Flash is not a smaller Hy4 for the same jobs. Billing follows the ID you send: hy4-flash is the cheap tier, hy4 the flagship, hy4-preview the August checkpoint.
Hy4 Flash is live — what shipped on November 16
The November 4 Hy4 announcement left Flash unpriced; the November 16 release post and same-day TokenHub listing closed that gap (ITHome, Sina Finance, LLMLearner specs).
- Tencent Cloud TokenHub, model ID
hy4-flash— live. - WorkBuddy, Yuanbao and Tencent apps — with WorkBuddy free through November 30.
- OpenRouter — planned, not live. Only
tencent/hy4is listed as of November 16; use TokenHub's Singapore endpoint until OpenRouter adds Flash.
Specs that explain why Flash costs one-tenth of Hy4
Hy4 Flash totals 224B parameters including 64B Engram parameters, with 12B active per token, in a mixture-of-experts layout (LLMLearner, Sina). Context window is 1M tokens (1,048,576), input is text plus image, output is text.
What matters for the bill: KV cache is 1/6 of Hy4 and 1/24 of Hy3, with megakernel, 4-bit quantization and dflash acceleration for decoding above 150 tokens/s. Multimodal image handling, chart parsing and visual math run on the same endpoint.
Weights are announced, not shipped: unlike Apache 2.0 Hy4-preview, Flash has no public checkpoint, date or license as of November 16.
Hy4 Flash API pricing in one table
TokenHub publishes separate mainland (CNY) and international (USD) catalogs — regional schedules, not conversions. Flash promo runs to November 30 at 12:00 Beijing time (LLMLearner); flagship promo runs to December 31 at 23:59 Beijing time (CostMyTokens verification, ChinaModelAPI).
| Tier | Input / 1M | Output / 1M | Cache read / 1M | Valid |
|---|---|---|---|---|
| Flash list (CNY) | ¥0.50 | ¥2.00 | ¥0.02 | standard |
| Flash promo (CNY) | ¥0.25 | ¥1.00 | ¥0.01 | to Nov 30, 12:00 Beijing |
| Flash list (USD) | $0.070 | $0.281 | $0.003 | standard |
| Hy4 list (CNY) | ¥6.00 | ¥18.00 | ¥0.30 | standard |
| Hy4 promo (CNY) | ¥3.00 | ¥9.00 | ¥0.15 | to Dec 31, 23:59 Beijing |
| Hy4 list (USD) | $0.834 | $2.501 | $0.042 | standard |
| Hy4 promo (USD) | $0.417 | $1.2505 | $0.021 | to Dec 31 |
Worked example at Flash promo: 100K fresh input + 500K cached input + 5K output = 0.1 x ¥0.25 + 0.5 x ¥0.01 + 0.005 x ¥1.00 = ¥0.035.
Per-task cost is the real gap. Tencent reports roughly 1/20 of Hy4, 1/13 of Hy4 preview and 1/8 of DeepSeek-V4.1-Flash (max) (Sina). Community math on the launch thread, derived from Tencent's blind test of 85 internal users over 259 tasks (LLMLearner), put it at ¥0.26 per task versus ¥4.73 for Claude Haiku 5.5 (high) and ¥1.20 for DeepSeek-V4.1-Flash, satisfaction 2.79 vs 2.81 (@alphaw0ng breakdown). No independent table exists yet — treat it as a vendor test with community arithmetic.
Cache decides agent bills: cache-read is 4–5% of fresh input (¥0.02 vs ¥0.50; $0.003 vs $0.070).
"Is it cutting-edge model? No, not at all. But this is the key to makes workbuddy the Doubao of the working agent. Just 200B-parameter means they can flood the mass market with very low-cost tokens enough to handle relatively simple tasks." — @LeroyLi311063, launch-day reaction
Flash vs Hy4 vs Hy4 Preview: pick by workload
| Hy4 Flash | Hy4 (GA, Nov 4) | Hy4 Preview (Aug 28) | |
|---|---|---|---|
| Params | 224B total / 12B active | undisclosed (preview ref: 770B / 49B) | 770B / 49B |
| Context | 1M | 1M — 960K max input, 64K max output (setup guide) | 1M |
| Modalities | text + image in, text out | text + image in, text out, computer use | text, early checkpoint |
| TokenHub ID | hy4-flash | hy4 | hy4-preview |
| List input/output | ¥0.5 / ¥2.0 | ¥6 / ¥18 ($0.834 / $2.501) | ¥6 / ¥18 |
| Best for | search, docs, slides, simple frontend, everyday computer use | long-horizon software, complex agents, finance research | testing open weights (Apache 2.0) |
Flagship context matters because Flash sits below it. In Tencent's Hy4 benchmark appendix, Hy4 trails top proprietary runs on Terminal-Bench 4.0 (44.4 vs ~66 for Opus 5.5-class) and ProgramBench (30.0 vs 56.5+). For SWE-bench-style or multi-hour terminal agents, the ¥0.25 promo input price does not make Flash the right model. Flagship rates are tracked in our Hy4 Preview API pricing guide and cheapest LLM API.
Call hy4-flash in 10 minutes
TokenHub is OpenAI-compatible with /v1/chat/completions, /v1/responses and Anthropic /v1/messages (endpoint guide). Use a TokenHub key, not a Yuanbao or WorkBuddy session token. Pick Guangzhou https://tokenhub.tencentmaas.com/v1 or Singapore https://tokenhub-intl.tencentmaas.com/v1, enable the model service in the console — a disabled service returns 402 per the same guide — then send hy4-flash.
curl https://tokenhub-intl.tencentmaas.com/v1/chat/completions \
  -H "Authorization: Bearer $TOKENHUB_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "hy4-flash",
    "messages": [{"role": "user", "content": "Summarize this 80-page PDF in 10 bullets"}]
}'from openai import OpenAI
client = OpenAI(api_key="YOUR_TOKENHUB_API_KEY",
base_url="https://tokenhub-intl.tencentmaas.com/v1")
resp = client.chat.completions.create(
model="hy4-flash",
messages=[{"role": "user", "content": "Hello"}],
)
print(resp.choices[0].message.content)Flash max output is undisclosed; Hy4 documents 64K — do not assume Flash inherits it. Check the console model page before planning 100K+ generations.
The routing rule: Flash by default, Hy4 for the hard 5%
| If your workload is… | Use | Why |
|---|---|---|
| Docs, slides, spreadsheets, meeting prep, deep search | hy4-flash | Near-Haiku satisfaction at ~¥0.26/task in Tencent's test |
| High-volume agents with stable long prefixes | hy4-flash | 4–5% cache ratio compounds fast |
| Simple frontend, everyday computer use | hy4-flash | Positioned here by Tencent; >150 tps helps interactivity |
| Long-horizon coding, terminal agents, program synthesis | hy4 | Flash is explicitly not positioned here |
| Self-hosting today | hy4-preview weights | Only preview has downloadable Apache 2.0 weights |