The Qwen4 Max API is now pay-as-you-go, not just a Token Plan preview, at $1.50 input and $4.50 output per 1M tokens with a 1M-token context window. Build on qwen4-max now, because qwen4-max-preview retires on November 25, 2026.
Qwen4-Max API at a glance: live since November 16, 2026
Alibaba made Qwen4-Max generally available on November 16, 2026 on Alibaba Cloud Model Studio as qwen4-max, after a Token Plan-only preview that started November 11. The launch was announced by @Alibaba_Qwen as a new MoE architecture with native vision and a 1M-token context window, with the API live on QwenCloud. QwenCloud docs mirror Model Studio for international access; use the Model Studio endpoint for your region (QwenCloud docs).
| Item | Qwen4-Max (qwen4-max) |
|---|---|
| Status | GA since Nov 16, 2026; preview qwen4-max-preview runs Nov 11–Nov 25, 2026, then retired |
| Input / output | $1.50 / $4.50 per 1M tokens (Singapore international) |
| Cache read | $0.075 per 1M tokens |
| Other regions | $1.413 / $4.24 per 1M tokens in US (Virginia), Frankfurt, Tokyo, Hong Kong |
| Context | 1M tokens; max input listed as 991K tokens |
| Max output | 131,072 tokens without thinking; 262,144 tokens for thinking plus answer |
| Input modes | Text, images, video |
| API style | OpenAI-compatible and Anthropic-compatible; tool calling, structured JSON output, web search, caching, batch, fine-tuning |
| Regions | Singapore, US (Virginia), Frankfurt, Tokyo, Hong Kong, Beijing; batch jobs Beijing only |
| Trial | New Singapore accounts get 1M free tokens for 90 days |
Pricing and limits above come from Alibaba Cloud Model Studio documentation as reported on November 16, 2026 (pricing and QwenCloud docs). Example: 100K input + 10K output in Singapore costs about $0.15 + $0.045 = $0.195.
What actually changed from Qwen3.8-Max
Qwen's announcement, citing Artificial Analysis figures, puts Qwen4-Max at an Intelligence Index of 43 — 9 points above Qwen3.8-Max (xhigh) and 3 points below Kimi K3.1 Pro — with an average cost of $3.27 per task, roughly one-third of Qwen3.8-Max, and 39% fewer output tokens.
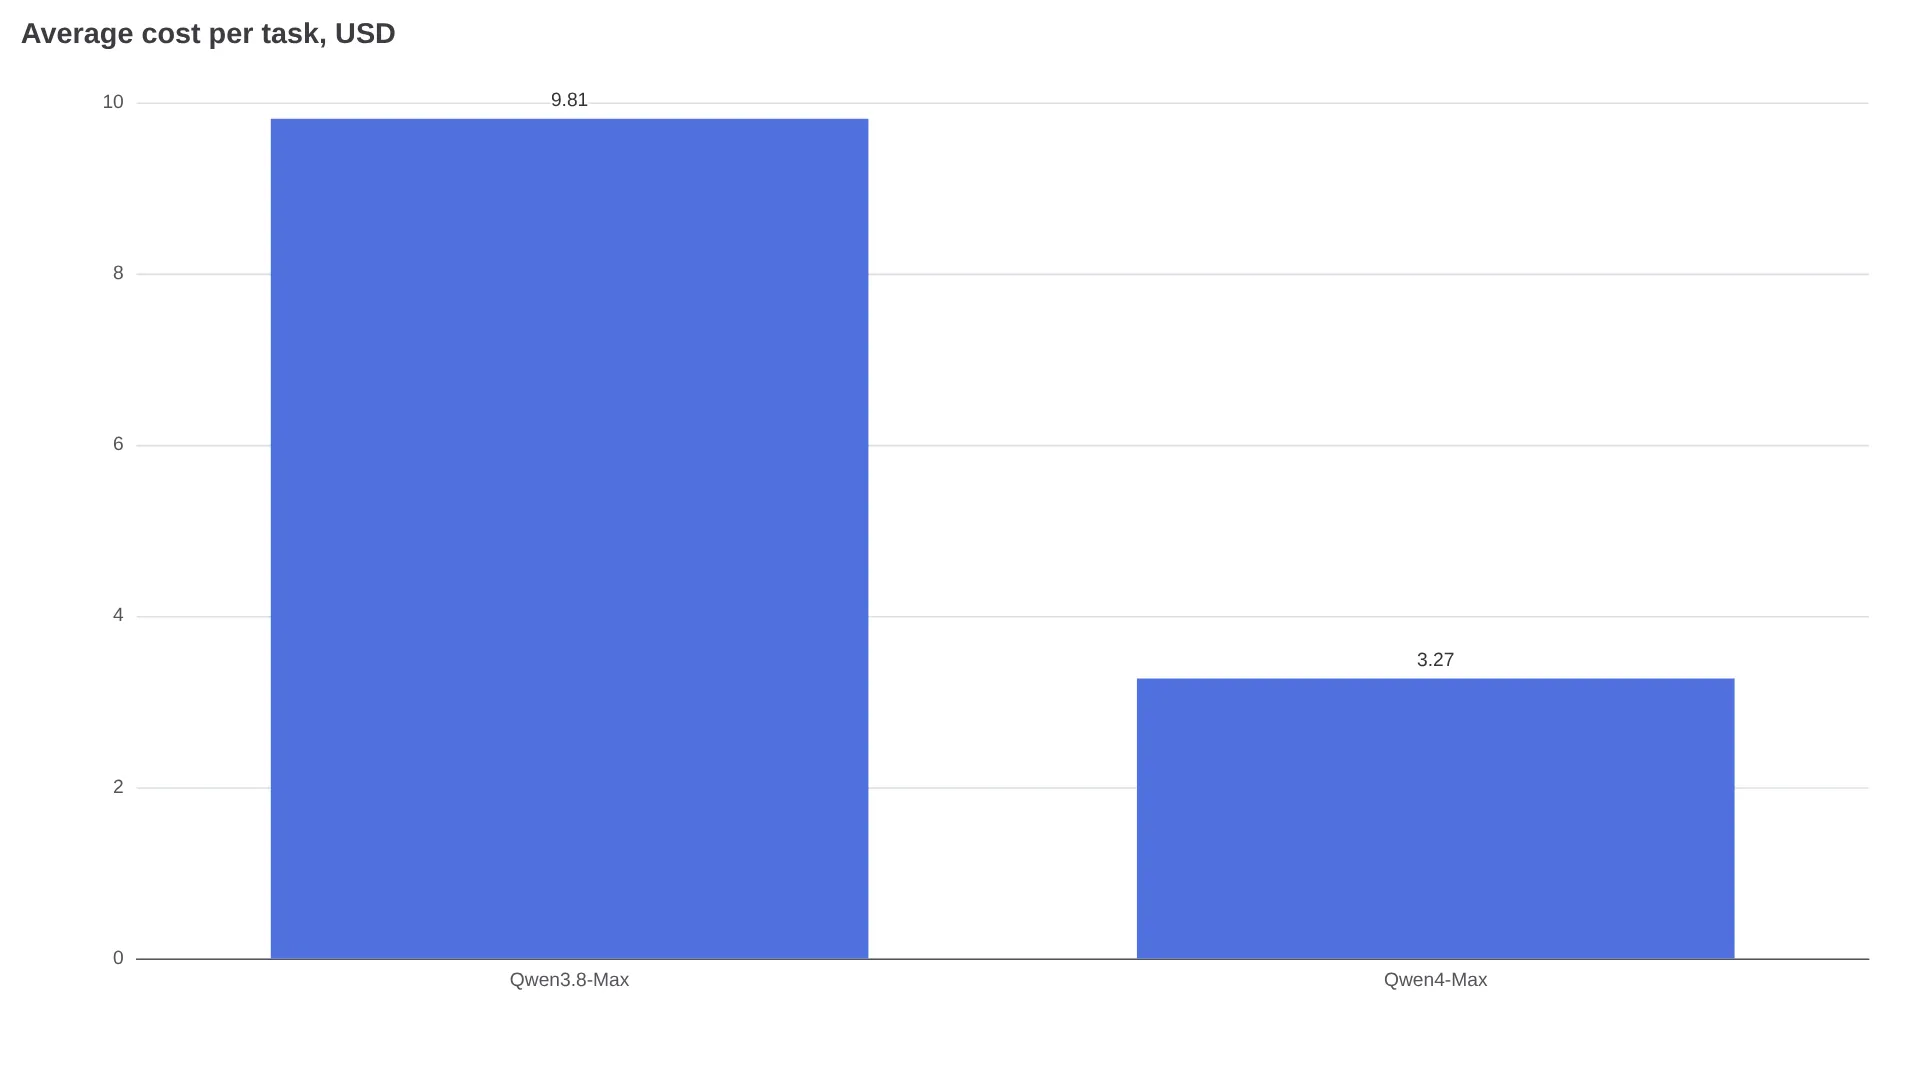
Two savings stack: the per-token price in the table above and fewer tokens per task (up to about 50% fewer in Qwen's internal evaluation). A 1M-token sweep with cache reuse benefits most, because implicit cache reads are $0.075 per 1M, stated as 70% cheaper than Qwen3.8-Max cache.
Under the hood, Qwen4-Max uses a native-vision MoE backbone (2.4T total parameters, 71B active, 328B N-gram embedding). While Qwen's blog cites Artificial Analysis scores, AI First Look and AICoder note that full benchmark tables and public AA leaderboard listings were not yet live on Nov 16.
Related reading on the predecessor: Qwen3.8-Max API pricing and Qwen3.8-Max vs Kimi K3.
Specs and limits that change your bill
Three limits matter more than the 1M headline.
Context vs usable input. The window is 1M tokens, but QwenCloud lists maximum input at 991K tokens. Budget a safety margin and test mid-context recall for retrieval-heavy work.
Output and thinking share the budget. Without thinking, maximum output is 131,072 tokens. With thinking on, thinking plus answer share a 262,144-token budget, so heavy reasoning eats answer space. The preview allowed 393,216 tokens shared by thinking and answer, per XenoSpectrum's preview spec rundown, so do not hard-code preview limits into production.
Thinking defaults changed. Thinking is on by default. The GA model defaults to high, with low and xhigh also available; the preview defaulted to xhigh, per AI First Look's spec table. If latency feels high, drop reasoning_effort to low first.
Multimodal input covers text, images, and video. Preview video submission caps were 2 hours, 2 GB, and 64 videos per request, per XenoSpectrum's preview spec rundown — submission limits, not a comprehension guarantee. Test long-video recall on your own files.
For cost control, request structured JSON output to cap rambling and reuse long context through cache reads ($0.075 per 1M in Singapore). AICoder's launch notes also list five-minute explicit cache creation at $1.875 per 1M where supported.
Calling qwen4-max with the OpenAI SDK
Model Studio supports OpenAI Chat Completions, Responses, and Anthropic Messages API shapes, per Alibaba Cloud's model docs. Use qwen4-max for pay-as-you-go backends; qwen4-max-preview is Token Plan only.
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("QWEN_API_KEY"),
    # Singapore/international endpoint:
    base_url="https://dashscope-intl.aliyuncs.com/compatible-mode/v1",
    # China/Beijing endpoint: https://dashscope.aliyuncs.com/compatible-mode/v1
)

resp = client.chat.completions.create(
    model="qwen4-max",
    messages=[
        {"role": "user", "content": "Summarize this release in 3 bullets."}
    ],
    extra_body={"reasoning_effort": "high"},
)
print(resp.choices[0].message.content)
Match the key and endpoint to the same Model Studio region. Request response_format={"type": "json_object"} or a JSON Schema where supported, and validate large structured outputs.
Pay-as-you-go vs Token Plan vs chat apps: which route to pick
| Route | Best for | Key constraint |
|---|---|---|
Model Studio pay-as-you-go (qwen4-max) | Apps, backends, batch | Per-token billing; check region endpoint and key |
Token Plan (qwen4-max-preview) | Interactive coding in Claude Code, Cline, Cursor, OpenCode | Interactive use only; no production automation, batch scripts, or backend embedding; Singapore region only; ends Nov 25, 2026 24:00 UTC+8 |
| Qwen Chat, QwenWork, QwenStudio, Qoder | Trying prompts, docs work, agentic IDE without wiring keys | Availability and credit rates shown in-app; not an API contract |
The Token Plan is a monthly credit pool for interactive development. Apidog's Token Plan breakdown lists individual tiers from Lite at $3 event / $8 list with 20,000 credits up to Pro at $43 event / $51 list with 200,000 credits, with keys starting with sb-sp-. Sharing keys, running background jobs, or embedding the key in a shipped backend violates the terms. For prompt-level tries, Apidog and XenoSpectrum list Qwen Chat, QwenWork, QwenStudio, and Qoder as evaluation routes, with availability shown in-app and varying by account.
Migrate before November 25, 2026:
- Change the model string from
qwen4-max-previewtoqwen4-max. - Move from the Token Plan base URL and key to a Model Studio pay-as-you-go key and regional endpoint.
- Re-test thinking defaults (
xhightohigh). - Re-measure output budgets (393K shared preview limit vs 131K/262K GA limits).
What early users report: fast greenfield builds, uneven agents
Small-sample tests collected by AI First Look report working one-prompt builds, including 20 of 20 hidden tests in about 2.5 minutes versus 17 minutes for Qwen3.8-Max, but the same roundup notes a game test where Qwen4-Max finished faster yet was still rated second overall.
Getting these failures constantly when trying to do any code generation.
— @bijanbowen, post (real user first impression, Nov 16, 2026; screenshot of repeated code-generation errors)
An early Chinese-language tester roundup (@weconomypistis) called price and per-task cost the biggest win but found terminal and agent operation a step behind Kimi with slower responses.
FAQ
Is Qwen4-Max open-weight?
No. Qwen4-Max is hosted only with no weights announced as of Nov 16, per AI First Look's tracker. Qwen says smaller Qwen4 models will get open weights later, per the Qwen4-Max announcement, with no date, sizes, or license yet.