 AIREITER
DeepSeek officially launched V4 Pro GA on August 13, 2026, posting full benchmark scores, MIT-licensed open weights, and three reasoning-effort levels. The operational headline for API users: the official pricing page confirms peak/off-peak billing starting August 16, 2026 at 16:00 UTC, with V4 Pro output tokens climbing from $0.87 to $1.98 off-peak or $3.96 peak per million.
What Shipped: V4-Pro-0813 With Benchmarks and Open Weights
The model behind the deepseek-v4-pro API alias is now DeepSeek-V4-Pro-0813, available on the DeepSeek app, web, and API. DeepSeek announced the launch on August 13, describing "significantly enhanced Agent capabilities" versus the April 24 preview build.
Architecture and specs:
| Item | DeepSeek-V4-Pro-0813 |
|---|---|
| Published model size | 1.7T parameters (model card; preview was 1.6T) |
| Context length | 1 million tokens |
| Maximum output | 384K tokens |
| Thinking modes | Non-thinking and thinking (thinking is default) |
| Reasoning effort levels | low, high, max |
| New decoding module | DSpark speculative decoding (7 speculative tokens) |
| API compatibility | OpenAI ChatCompletions, Responses API, Anthropic API, Codex |
| Concurrency limit | 500 |
| License | MIT |
The model card recommends temperature = 1.0 and top_p = 0.95 for agentic scenarios, with a 384K-token maximum output length at high and max effort.
Official GA Benchmarks
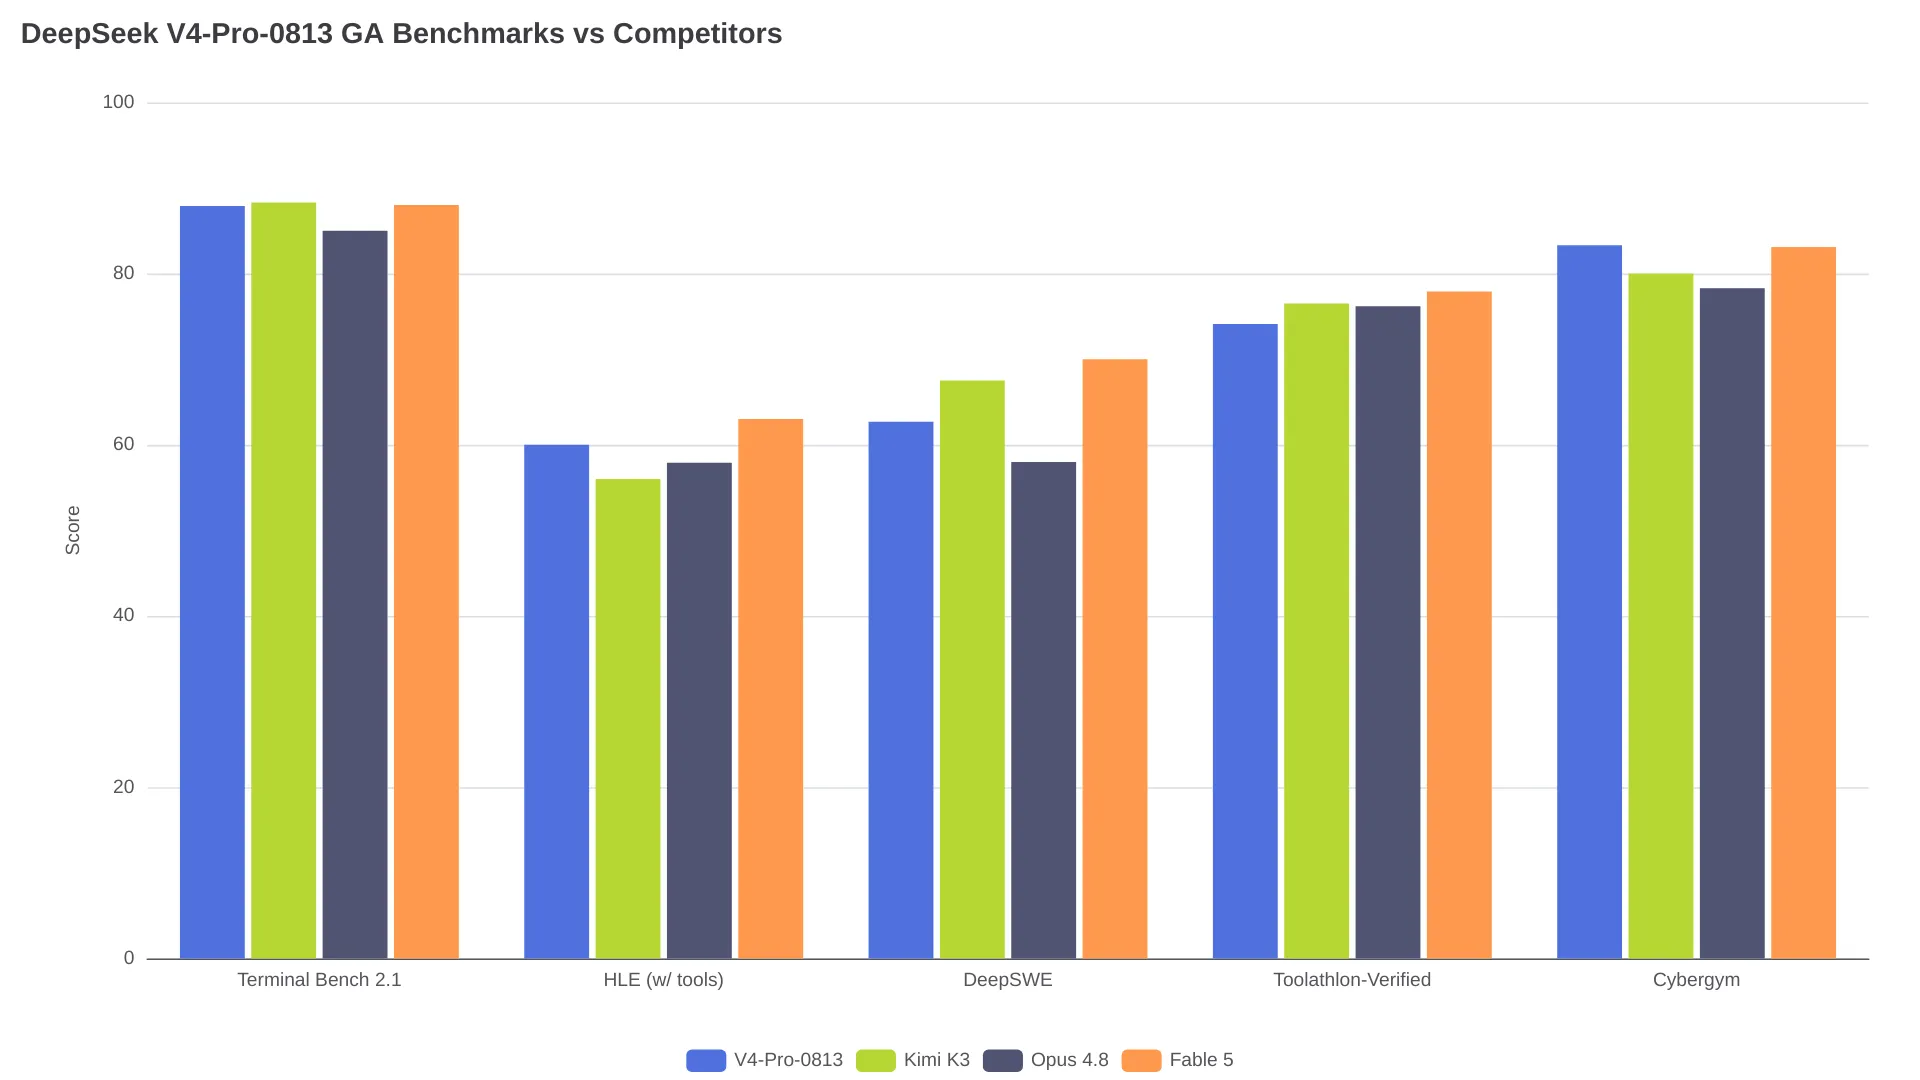
DeepSeek published ten benchmark comparisons on the model card. Code-agent tasks used DeepSeek Harness minimal mode at max reasoning effort. The last two rows (DSBench) are DeepSeek internal test sets. All scores below are from that model card.
| Benchmark | Pro-0813 | Flash-0731 | Pro Preview | Kimi K3 | Opus 4.8 | Fable 5 |
|---|---|---|---|---|---|---|
| HLE (no tools / w/ tools) | 42.7 / 60.0 | 37.8 / 51.5 | 37.7 / 48.2 | 43.5 / 56.0 | 49.8 / 57.9 | 53.3 / 63.0 |
| Terminal Bench 2.1 | 87.9 | 82.7 | 72.1 | 88.3 | 85.0 | 88.0 |
| DeepSWE | 62.7 | 54.4 | 12.8 | 67.5 | 58.0 | 70.0 |
| Toolathlon-Verified | 74.1 | 70.3 | 55.9 | 76.5 | 76.2 | 77.9 |
| Cybergym | 83.3 | 76.7 | 52.7 | 80.0 | 78.3 | 83.1 |
| NL2Repo | 61.5 | 54.2 | 38.5 | — | 69.7 | — |
| Agents' Last Exam | 25.7 | 25.2 | 16.5 | 27.6 | 25.7 | — |
| AutomationBench (Public) | 31.8 | 25.1 | 12.8 | 30.8 | 27.2 | 29.1 |
| DSBench-FullStack (internal) | 71.1 | 68.7 | 41.8 | 73.7 | 71.6 | 77.2 |
| DSBench-Hard (internal) | 67.2 | 59.6 | 31.1 | 63.0 | 71.7 | 68.3 |
The GA jump over preview is dramatic: DeepSWE went from 12.8 to 62.7, AutomationBench from 12.8 to 31.8. Against competitors, Pro-0813 leads on HLE with tools (60.0, ahead of Kimi K3's 56.0 and Opus 4.8's 57.9) but trails Kimi K3 and Fable 5 on DeepSWE, Terminal Bench, and Toolathlon-Verified. The two DSBench rows are vendor-internal and should not be weighted like independently maintained benchmarks.
Open Weights
The 0813 weights are live on Hugging Face under MIT license, with vLLM and SGLang deployment paths. The model card includes a vLLM serving example using DSpark speculative decoding, FP8 KV cache, and a single 4x GB300 node.
"Broadly competitive with the strongest proprietary models available." — DeepSeek V4-Pro model card, Hugging Face
Full Pricing Breakdown: What You Pay Before and After August 16
The pricing page lists both a current flat rate and a scheduled peak/off-peak rate effective August 16, 2026 at 16:00 UTC. Peak hours are 01:00–04:00 UTC and 06:00–10:00 UTC (Beijing 09:00–12:00 and 14:00–18:00). All other hours are off-peak. Off-peak is exactly half of peak.
DeepSeek V4 Pro (DeepSeek-V4-Pro-0813)
| Billing category | Current flat rate | Off-peak (Aug 16) | Peak (Aug 16) | Change at peak |
|---|---|---|---|---|
| Input, cache hit | $0.003625/M | $0.022/M | $0.044/M | +1,114% |
| Input, cache miss | $0.435/M | $0.66/M | $1.32/M | +203% |
| Output | $0.87/M | $1.98/M | $3.96/M | +355% |
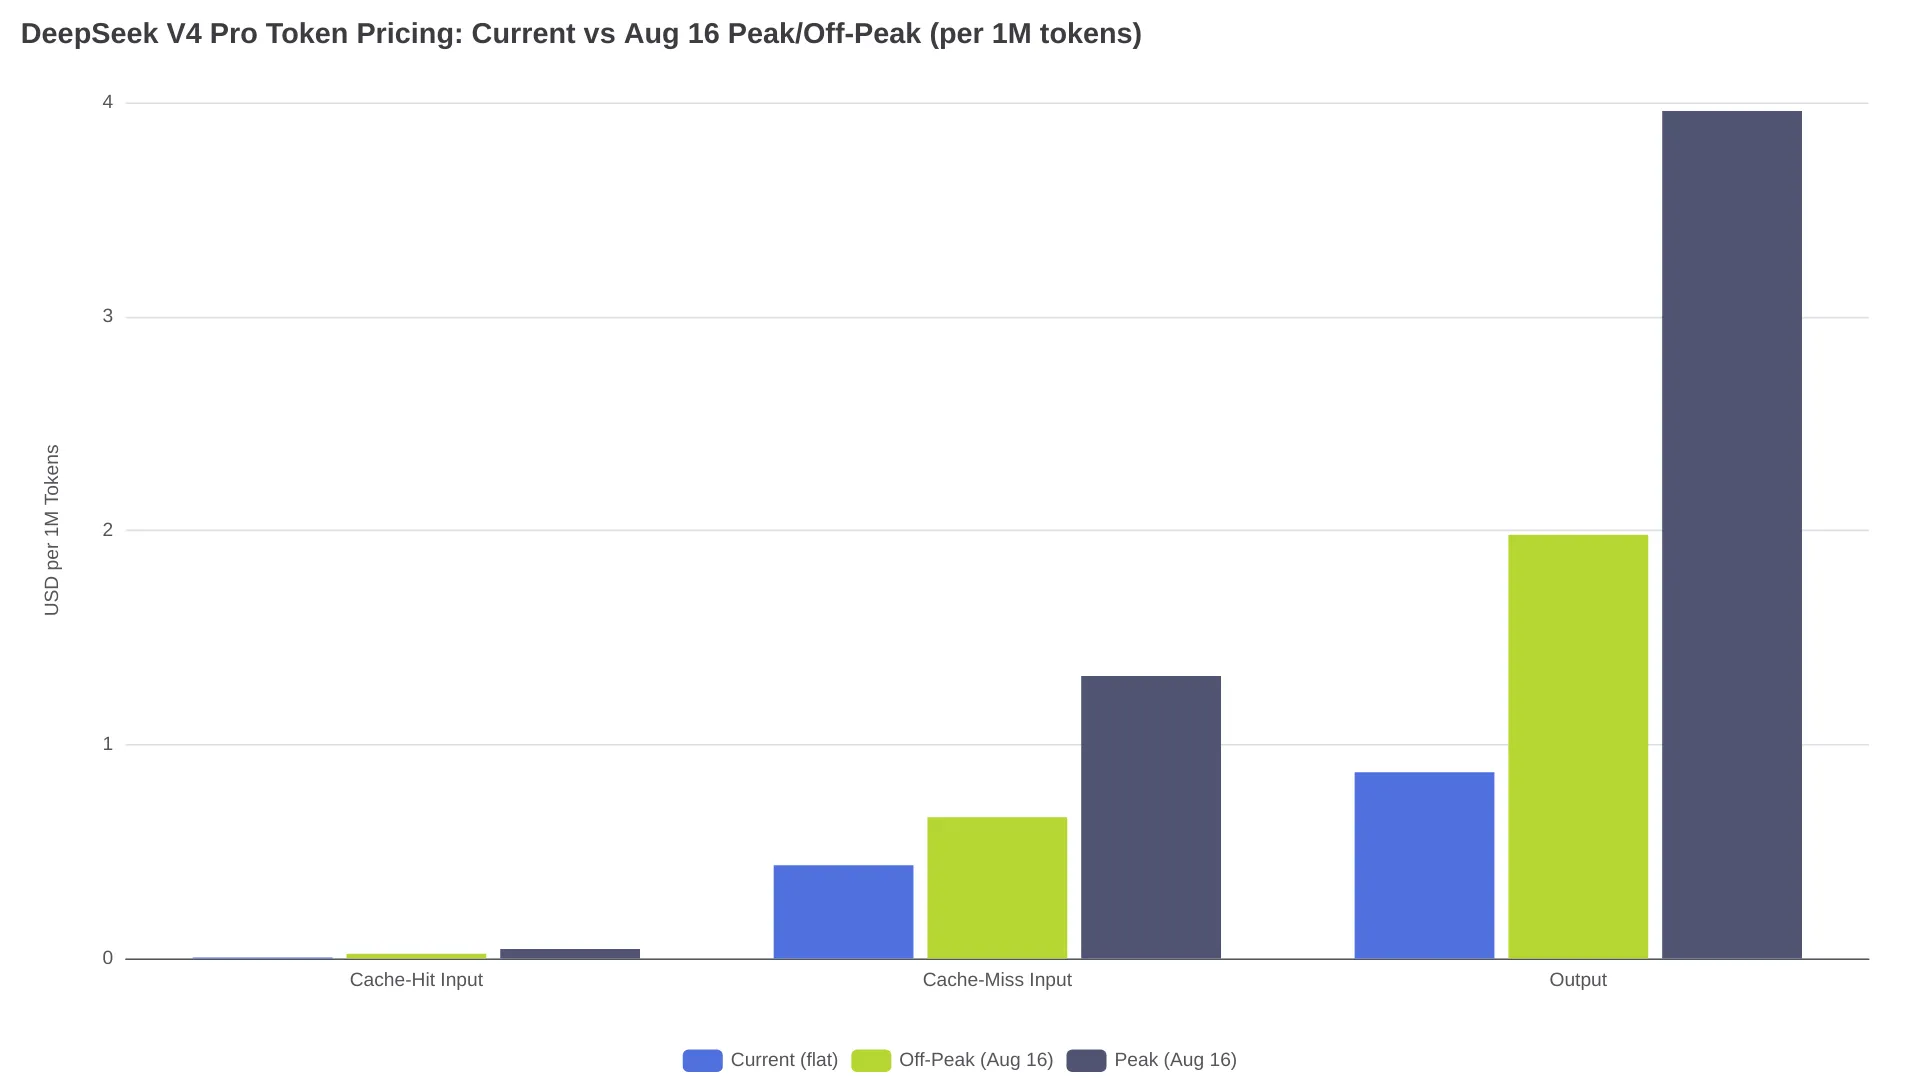
Peak output rises 4.6x. The cache-hit change is more disruptive for production agent workflows: the previous $0.003625/M rate was roughly 120x cheaper than cache-miss. After August 16, that ratio drops to 30x at both tiers (0.022 vs 0.66 off-peak, 0.044 vs 1.32 peak), while absolute cache-hit cost rises 6x to 12x.
DeepSeek V4 Flash (DeepSeek-V4-Flash-0731)
| Billing category | Current flat rate | Off-peak (Aug 16) | Peak (Aug 16) | Change at peak |
|---|---|---|---|---|
| Input, cache hit | $0.0028/M | $0.007/M | $0.014/M | +400% |
| Input, cache miss | $0.14/M | $0.22/M | $0.44/M | +214% |
| Output | $0.28/M | $0.66/M | $1.32/M | +371% |
Concurrency limit: 2,500 concurrent requests, five times Pro's allocation.
When Peak Hours Hit in Your Timezone
| Timezone | Peak window 1 | Peak window 2 |
|---|---|---|
| Beijing (UTC+8) | 09:00–12:00 | 14:00–18:00 |
| London (UTC+1) | 02:00–05:00 | 07:00–11:00 |
| New York (UTC-4) | 21:00–00:00 (prev day) | 02:00–06:00 |
| San Francisco (UTC-7) | 18:00–21:00 | 23:00–03:00 |
For US-based teams, peak windows fall mostly during overnight and evening hours. For teams in China or East Asia, peak hours align with standard business hours.
What This Costs You: Pro at 10,000 Calls/Day
Consider a production agent sending a 50K-token cached prefix with a 2K-token response per call.
| Cost component | Current flat | Off-peak | Peak |
|---|---|---|---|
| Cache-hit input (500M tokens) | $1.81 | $11.00 | $22.00 |
| Output (20M tokens) | $17.40 | $39.60 | $79.20 |
| Daily total | $19.21 | $50.60 | $101.20 |
| 30-day total | $576 | $1,518 | $3,036 |
Real workloads mix peak and off-peak calls, landing between these bounds. The same workload on Flash costs $7.00/day at current flat rates, ~$16.70/day at off-peak, and ~$33.40/day at peak. Flash peak ($33.40/day) exceeds Pro's current flat rate ($19.21/day), but Flash off-peak ($16.70/day) undercuts it.
Migration: Model IDs, Reasoning Control, and Version Pinning
Endpoint Retirement and Replacement IDs
The April 24 preview announcement stated that deepseek-chat and deepseek-reasoner would be "fully retired and inaccessible after Jul 24th, 2026, 15:59 (UTC Time)." Code referencing those strings should be updated.
| Old endpoint | What it routed to | Replacement |
|---|---|---|
deepseek-chat | V4 Flash, non-thinking | deepseek-v4-flash |
deepseek-reasoner | V4 Flash, thinking | deepseek-v4-flash (thinking) or deepseek-v4-pro |
Many teams assumed deepseek-reasoner delivered Pro-tier reasoning. It routed to Flash in thinking mode. Migrating to deepseek-v4-pro produces different output quality and a higher bill.
// Before (retired — fails)
{"model": "deepseek-reasoner", "messages": [...]}

// After
{"model": "deepseek-v4-pro", "messages": [...]}
Base URL stays https://api.deepseek.com. No other request structure changes.
Reasoning Effort Levels
V4-Pro-0813 introduces three reasoning effort levels: low for simple tasks, high for everyday agent work, max for complex problems. Thinking mode is on by default, and thinking tokens count toward output billing. A prompt that triggers 3,000 thinking tokens before producing a 200-token answer bills you for 3,200 output tokens at peak pricing — $0.0127 per call versus $0.0008 for the answer alone. The low level is the setting DeepSeek designates for simple tasks where extended thinking adds cost without value.
Version Pinning
The deepseek-v4-pro alias points to the current build and may update when DeepSeek ships future versions. For reproducible production behavior, check whether your provider supports dated model identifiers. Some third-party gateways offer pinned routes — verify in provider documentation which build each route serves before relying on it for production.
API Protocol Compatibility
Both models support OpenAI ChatCompletions and Anthropic API formats. The Anthropic endpoint is https://api.deepseek.com/anthropic. The Responses API and Codex compatibility are new in the GA build. Test both protocol paths if you encounter errors after migration.
Pro vs Flash: Which One After the Price Hike?
V4-Pro-0813 beats V4-Flash-0731 on all ten published metrics. The margins vary by task complexity:
| Benchmark | Pro 0813 | Flash 0731 | Gap |
|---|---|---|---|
| Terminal Bench 2.1 | 87.9 | 82.7 | 5.2 pts |
| DeepSWE | 62.7 | 54.4 | 8.3 pts |
| AutomationBench | 31.8 | 25.1 | 6.7 pts |
| Cybergym | 83.3 | 76.7 | 6.6 pts |
Choose V4 Pro when:
- Your agent loop sends a stable, large prefix repeatedly. Cache-hit savings still apply at a higher base rate
- You need Pro's larger parameter count for complex reasoning, multi-step tool use, or large-scale code generation
- Your workload tolerates the 500 concurrent request limit
Choose V4 Flash when:
- Your tasks are simple, high-volume, or latency-sensitive
- You need the 2,500 concurrent request limit for fan-out workloads
- The quality difference does not justify 3x higher output pricing
For a broader model-to-model breakdown, see our DeepSeek V4 Flash vs Pro comparison. To test the model without managing API keys, the V4 Pro chat page and V4 Flash chat page offer immediate access.
FAQ
Are the V4-Pro-0813 weights available for self-hosting?
Yes — MIT-licensed and available on Hugging Face with vLLM and SGLang paths (see Open Weights above for deployment details).
Should I move from V4 Flash to V4 Pro for the GA?
For most cost-sensitive workloads, Flash remains the better value. It trails Pro by margins ranging from 0.5 points (Agents' Last Exam) to 8.5 points (HLE with tools) across benchmarks, while costing 3x less for output. Move to Pro if your workload requires the full parameter count for complex multi-step reasoning or large-scale code generation.
How do I minimize the impact of the price increase?
Three levers: schedule batch jobs and deferrable agents outside peak hours (01:00–04:00 and 06:00–10:00 UTC); maximize cache hits by keeping prompt prefixes stable; route simple tasks to Flash or use low reasoning effort on Pro.
Does the peak/off-peak pricing apply to the DeepSeek app and website?
The official pricing page documents API token billing only. The listed schedule applies to direct API calls; gateway providers may pass it through, add markup, or use separate rates. Check the pricing page for current details.