 AIREITER
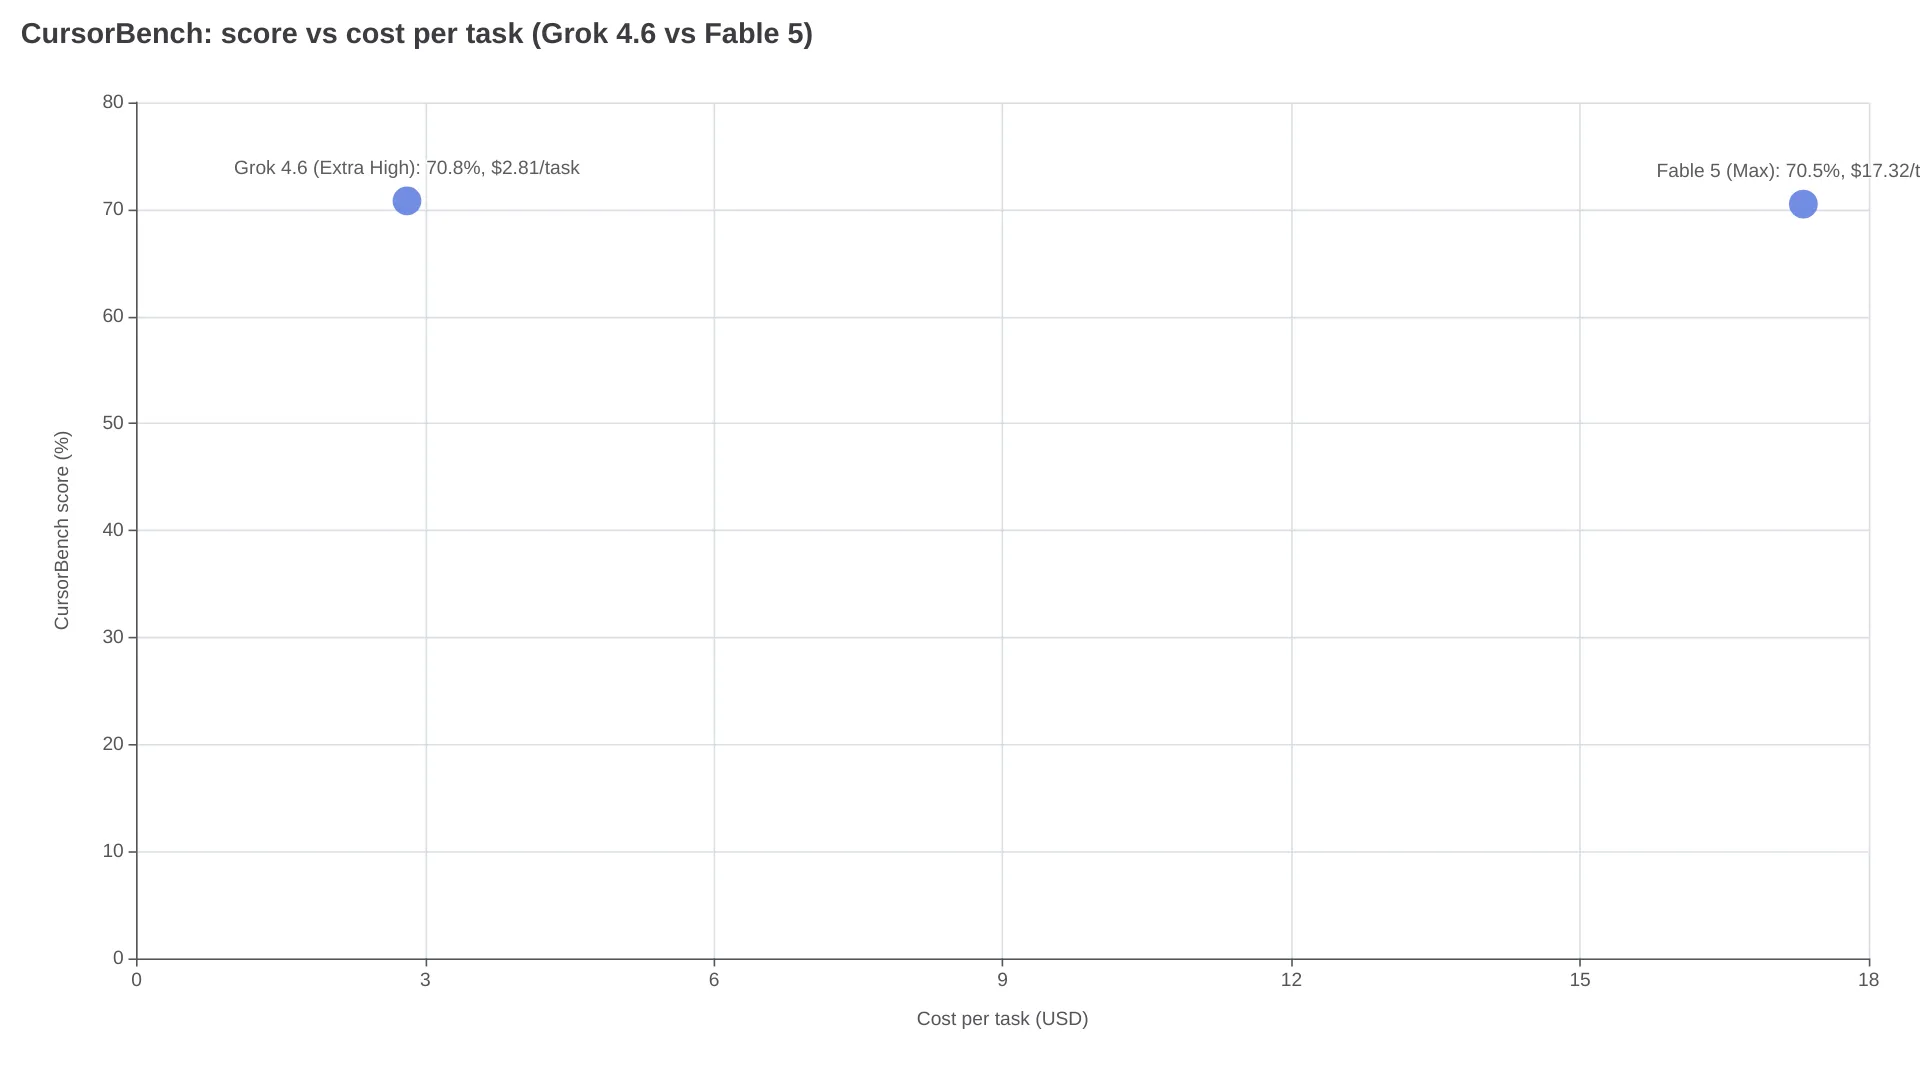
Grok 4.6 Extra High scored 70.8% on CursorBench at $2.81 per completed task; Fable 5 Max ran the same agent harness at 70.5% for $17.32 per task. That is a benchmark tie on the comparison coding agents run - and a 6x spread on what each task costs you. The one condition that keeps Fable 5 ahead: it still tops the broader Artificial Analysis intelligence index, and it carries twice the context window.
How Grok 4.6 closed the gap with Fable 5
Two months ago this comparison had a clear answer. In July 2026, Artificial Analysis scored Grok 4.5 at 56 on the Intelligence Index against Fable 5's 62 - a six-point gap. Grok 4.6, released in August 2026, gained an estimated five points to ~59 - roughly tying GPT-5.6 Sol - based on reported benchmark deltas, narrowing Fable 5's lead to about three.
On coding agents the gap closed further. Fable 5 entered Cursor in June 2026 setting a state-of-the-art 72.9% on CursorBench (r/accelerate), 8 points above the previous best. In the August head-to-head posted to r/cursor, after Grok 4.6's release, Grok 4.6 Extra High posted 70.8% against Fable 5 Max at 70.5% - inside the same agent harness, effectively a tie. One caveat worth holding onto came from a Cursor user who ran the comparison:
"Grok 4.6 made me wonder: how much of CursorBench is the model, and how much is the harness?" - r/cursor thread, August 2026
Benchmark scores measure the full agent stack - prompt scaffolding, tools, retries - not the base model alone, and Fable 5's 72.9% launch run and the 70.5% August figure came from different configurations, so treat both as directional.
Cost per task is where Grok 4.6 dominates
The per-task numbers from that August comparison are the real story:
| Metric (CursorBench) | Grok 4.6 Extra High | Fable 5 Max |
|---|---|---|
| Score | 70.8% | 70.5% |
| Cost per task | $2.81 | $17.32 |
| Steps per task | 46 | 72 |
Fable 5 needed 57% more agent steps to land at the same score; the extra steps and the reasoning tokens they carry line up with the cost gap. This is why developers who switched between the two started questioning the sticker-price lens entirely:
"$/token is becoming the wrong way to compare AI agents." - r/grok thread title, August 2026
The per-token list prices explain part of the spread. Fable 5 runs $10 input / $50 output per million tokens on the Anthropic API. Grok 4.5's published xAI API rate was $2 / $6 per million under a 200K-token prompt; xAI has not published a separate 4.6 rate card, and the r/grok community reports 4.6 landing at "Sol-level performance at a fraction of the API price." For the full Fable 5 rate card across tiers, see the Fable 5 API pricing breakdown.
Two things shrink that advantage in practice. Grok's pricing roughly doubles above 200K-token prompts ($4 / $12 per million at that tier, per xAI's published rates), and if your workflow leans heavily on Fable 5 anyway, there are structural ways to cut Fable 5 token costs before switching models.
Where Fable 5 still leads
| Area | The evidence | What it means for you |
|---|---|---|
| Intelligence index | Fable 5 remains #1 on the AA Intelligence Index: 62 vs roughly 59 for Grok 4.6 | Three points of the old six-point lead survived the 4.6 jump |
| Context window | Fable 5 exposes 1,000,000 tokens of context; Grok sits at 500,000 | A large repo plus task history fits in one pass, and Grok's price edge narrows at the above-200K tier |
| Hardest-task reliability | In TryAI's build test Fable 5 rendered the 3D Rubik's Cube on the first attempt and produced the best SVG; Grok 4.5 needed a re-run. Goldie Bench put Fable 5 ahead 20-17 across 47 one-shot tasks, winning shader and GPU-physics builds by 0.8-1.6 points | When the task is ambiguous and one-shot, Fable 5's reasoning ceiling shows |
Speed, latency, and throughput
TryAI's measured numbers, same provider routing, 400-token cap, three runs per prompt type:
| Metric | Grok 4.5 | Fable 5 |
|---|---|---|
| Time to first token | 0.44 s | 3.47 s |
| Throughput | 110 tok/s | 28 tok/s |
| Cost per reply | $0.00002 | $0.00009 |
| Success rate | 100% | 100% |
Grok generated 110 tok/s - roughly double GPT-5.5 and Opus 4.8, and about four times Fable 5's 28 tok/s. Artificial Analysis adds a harsher Fable 5 number at max-effort reasoning: 113.68 seconds to first answer token versus 8.68 for Grok - though once streaming starts, Fable 5 decodes slightly faster (63.1 vs 58.9 tok/s). Practical translation: Grok feels snappy in interactive loops; Fable 5 front-loads long thinking and pays for it in wall-clock time.
Access, subscriptions, and agent tooling
Fable 5 ships through the Anthropic API, Claude Code, and Cursor, with flat-rate Claude Pro subscriptions covering most non-API use. The Claude Code ecosystem - CLAUDE.md, plugins, skills, MCP servers - has years of maturity.
Grok 4.6 is available via the xAI API and the Grok Build CLI (curl -fsSL https://x.ai/cli/install.sh | bash), with X Premium bundling chat access. Per ClockedCode, Grok Build reads existing CLAUDE.md files, Claude Code plugins, skills, MCP servers, agents, and hooks with zero configuration, runs headless with a -p flag for CI, and exposes an Agent Client Protocol for embedding. The ecosystem is younger, but that Claude Code compatibility keeps migration cost near zero for compatible setups.
One billing reality for both: Claude Pro and X Premium subscribers pay flat rates, so usage limits under your actual workload matter more than the rate card.
Pick by scenario
| Your situation | Pick | Why |
|---|---|---|
| High-volume, well-specified coding tasks | Grok 4.6 | $2.81/task vs $17.32 at tied CursorBench scores |
| Correctness-critical work in a large repo | Fable 5 | 1M context window, #1 intelligence index, best first-attempt reliability |
| Interactive agent sessions, fast iteration | Grok 4.6 | 0.44 s first token, 110 tok/s |
| Ambiguous one-shot builds, hardest reasoning | Fable 5 | Won TryAI's hardest task and Goldie Bench head-to-heads |
| Budget-capped API spend | Grok 4.6 | Output tokens at roughly one-eighth of Fable 5's price |
My read: default to Grok 4.6 for bounded, repetitive work, and reserve Fable 5 for tasks where a wrong answer costs more than the tokens. Teams with real volume should run both and route by representative task size, retry rate, and completed-task cost - cheaper than committing to either one exclusively.
FAQ
Is Grok 4.6 better than Fable 5 for coding?
On CursorBench they are tied - 70.8% for Grok 4.6 Extra High versus 70.5% for Fable 5 Max in the August comparison. Fable 5 still leads the broader Artificial Analysis intelligence index (62 vs ~59) and wins the hardest one-shot tasks, so "better" depends on whether your bottleneck is cost per task or correctness ceiling.
Is Grok 4.6 cheaper than Fable 5?
Yes, by roughly 6x per completed CursorBench task ($2.81 vs $17.32). The per-token comparison leans on Grok 4.5's published rate ($6 output vs Fable 5's $50 per million) because xAI has not released a separate 4.6 card; that gap narrows above 200K tokens, where Grok pricing roughly doubles.
Which model has the bigger context window?
Fable 5, at 1,000,000 tokens versus Grok's 500,000. For workloads that hold an entire codebase in context, that difference can outweigh Grok's price advantage.
Can Grok Build use my Claude Code setup?
Yes. Grok Build automatically reads CLAUDE.md, Claude Code plugins, skills, MCP servers, agents, and hooks with no porting, and adds its own .grok/ directory for Grok-specific config.
Are Grok 4.5 benchmarks a good proxy for Grok 4.6?
Not for capability. Grok 4.6 gained about five Intelligence Index points relative to 4.5, turning a six-point deficit to Fable 5 into roughly three, and tied Fable 5 Max on CursorBench where 4.5 trailed clearly. The speed and per-token pricing figures in this article are Grok 4.5 measurements, since no equivalent Grok 4.6 figures are published yet.
The trade-off that won't resolve
No benchmark in this comparison settles whether the cost lead holds when the repository is 50,000 lines, the ticket is ambiguous, and a failed attempt costs an hour of debugging. Fable 5's 1M context and higher intelligence ceiling exist precisely for that case - expensive certainty against Grok 4.6's cheap steps, and a split wide enough that most teams keep both active.
Related reading: Grok 4.6 vs GPT-5.6 · Grok 4.6 vs Opus 5 · Claude Sonnet 5 vs Fable 5