 AIREITER
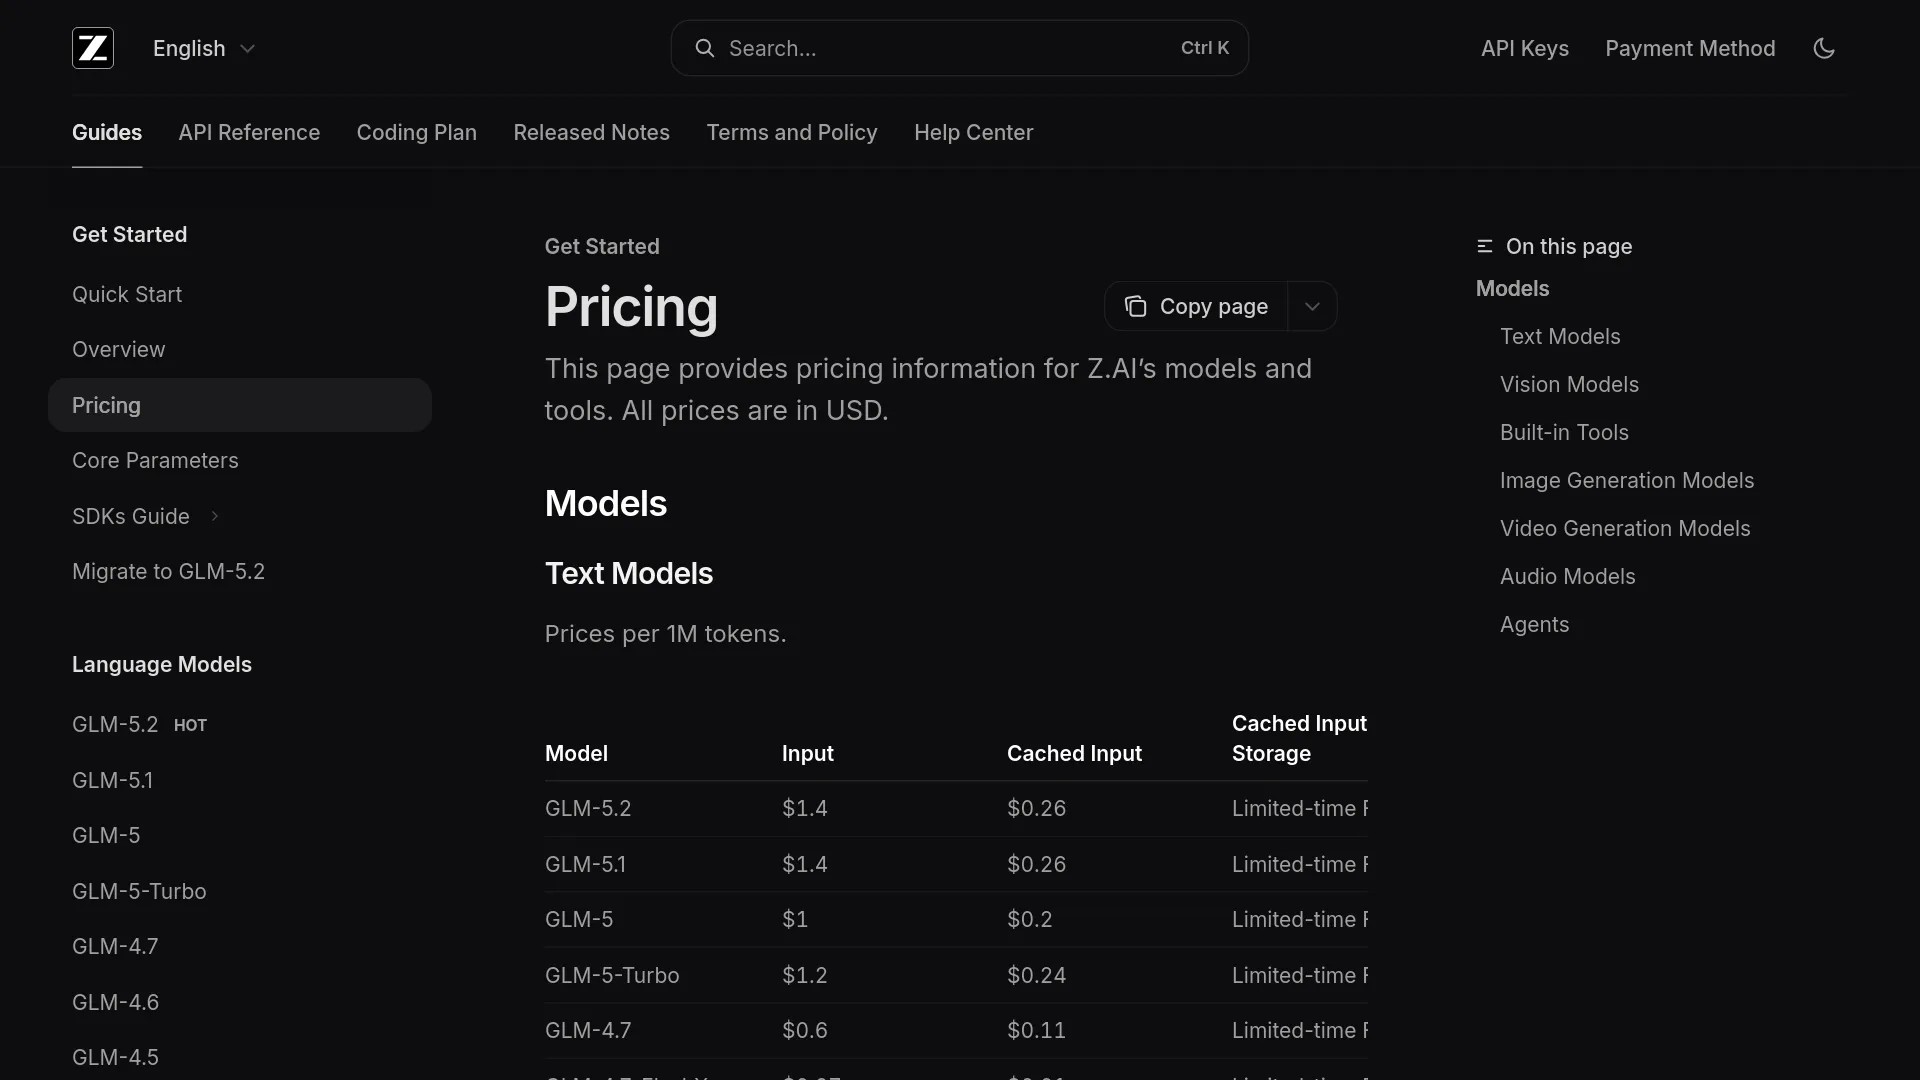
GLM-5.3's coding gains are announcement claims, while the public Z.ai API reference and price table checked on August 14, 2026 still list glm-5.2, not glm-5.3. Z.ai API reference Z.ai pricing
The short answer: upgrade the evaluation, not the production route
GLM-5.3 is worth a controlled pilot for difficult coding-agent work when a verified access channel exposes it. GLM-5.2 should remain the production baseline until GLM-5.3 has a confirmed model identifier, operating terms, and better results on your own acceptance tasks.
Z.ai's GLM-5.3 announcement, as reproduced in a contemporaneous release discussion, says the model keeps the GLM-5.2 base and gains capability through post-training. It claims a 50% gain on Z.ai Code Bench and leading open-source results on Terminal-Bench 3.0 and Agents' Last Exam, but the cited release discussion does not provide raw scores, configurations, pricing, context length, or a license. GLM-5.3 release discussion
What is actually different between GLM-5.2 and GLM-5.3?
GLM-5.2 is a documented text model with a production API surface. Z.ai lists a 1M-token context window, a 128K maximum output, function calling, structured output, caching, MCP support, and an MIT-licensed checkpoint on Hugging Face. GLM-5.2 documentation GLM-5.2 model card
GLM-5.3 is positioned as a coding and cyber-defense post-training update. The available release material says the base model is unchanged from GLM-5.2 and says weights are planned after safety evaluation and hardening; it does not establish that GLM-5.2's context limit, output limit, MIT terms, or public API support carry forward unchanged. GLM-5.3 release discussion
| Decision field | GLM-5.2 | GLM-5.3 |
|---|---|---|
| Base-model relationship | Published open-weight model card | Z.ai says it uses the GLM-5.2 base; gains are from post-training |
| Coding evidence | Vendor table reports 62.1 on SWE-bench Pro and 81.0 on Terminal-Bench 2.1 | Z.ai claims 50% better on its internal Code Bench; no absolute score in release material |
| Long-context specification | 1M context and 128K maximum output documented | Not specified in release material |
| Public API documentation | glm-5.2 is listed in the chat-completions reference | glm-5.3 is not listed in the reference checked August 14, 2026 |
| Direct API list price | $1.40 input, $0.26 cached input, $4.40 output per MTok | Not listed in the public price table checked August 14, 2026 |
| Weights and license | Downloadable GLM-5.2 weights under MIT | Weights described as pending safety evaluation; license not stated |
GLM-5.2 fields are documented; GLM-5.3 fields remain unconfirmed where the release material provides no API, pricing, weight, or license details. Z.ai API reference Z.ai pricing GLM-5.2 model card
Why the 5.3 coding claim is not yet a drop-in migration signal
The 50% Code Bench claim lacks the task set, agent harness, token budget, and absolute scores needed to predict results on a repository's acceptance tests. GLM-5.3 release discussion
“The harness still matters more than the model.” Source: Semgrep Security Research
Semgrep's GLM-5.2 IDOR experiment illustrates the point: in one dataset and one run, its prompt-only GLM-5.2 configuration scored 39% F1, while its purpose-built multimodal harness scored 61% with GPT-5.5. The authors caution against generalizing that ordering beyond the tested task, so a GLM-5.3 pilot should keep the existing scaffold unchanged. Semgrep methodology and results
GLM-5.2's reported FrontierSWE, DeepSWE, and Terminal-Bench results are useful for selecting test cases, but its model card also documents model-specific harnesses, token budgets, and evaluation settings. GLM-5.2 model card
Availability is the current deciding constraint
GLM-5.2 is the only version in this comparison with a clear public API contract at the time checked. The Z.ai chat-completions reference uses glm-5.2 in its request example, lists it among available text-model values, and says reasoning_effort is supported only by GLM-5.2. Z.ai chat-completions reference
Community access reports do not establish a supported public API integration. GLM 5.3 community thread
A three-task upgrade gate for GLM-5.2 users
GLM-5.2 users should test a new version as an agent-system change, even when the base model is shared. Do not modify your prompt, tools, permissions, or retry policy during the first comparison.
- Pin three representative tasks. Use one bounded bug fix with a test oracle, one cross-file refactor with forbidden-change checks, and one long-context review or migration task. Freeze the repository commit, task text, tools, and acceptance criteria.
- Verify the 5.3 route before sending traffic. Record the provider, exact model ID, context and output limits, token price, rate limit, data-handling terms, and failure behavior from that provider's current documentation. Do not infer these fields from GLM-5.2 or from a coding-plan screenshot. Z.ai API reference Z.ai pricing
- Compare accepted outcomes, not a single score. Run the same scaffold against both versions and log acceptance rate, test failures, forbidden edits, wall time, input/cache/output tokens, retries, and human repair time. Route only the task class where GLM-5.3 improves accepted outcomes without an unacceptable cost or reliability regression. Semgrep methodology
Pick the version by deployment state
| Your state | Choose now | Next action |
|---|---|---|
| Production app using Z.ai's documented public API | GLM-5.2 | Keep the current model string and baseline metrics |
| Confirmed access to GLM-5.3 for difficult code-agent tasks | Controlled GLM-5.3 pilot | Run the three-task gate with the same harness |
| Local or private deployment | GLM-5.2 | Wait for GLM-5.3 weights, license, and serving guidance to be published |
| Screenshot, PDF, or image understanding | Neither result settles the need | Evaluate a documented vision model; GLM-5.2 is text-to-text |
Pilot 5.3 only when documented access and better accepted results justify replacing the 5.2 baseline. GLM-5.3 release discussion GLM-5.2 documentation
FAQ
Is GLM-5.3 a new base model?
Z.ai's release claim says GLM-5.3 uses the same base as GLM-5.2 and attributes its gains to post-training. The cited release material does not provide a new architecture or parameter specification. GLM-5.3 release discussion
Is GLM-5.3 available through the public Z.ai API?
The public Z.ai reference checked on August 14, 2026 does not list glm-5.3; confirm a provider's current documentation before integrating a 5.3 route. Z.ai chat-completions reference
Does GLM-5.3 keep GLM-5.2's 1M context and MIT license?
That has not been established by the cited GLM-5.3 release material. GLM-5.2's 1M context and MIT license are documented on its official model card; shared base-model lineage does not prove equivalent release terms. GLM-5.2 model card GLM-5.3 release discussion