 AIREITER
ERNIE 5.5 Flash Preview offers live API access, but Baidu says post-training is incomplete and the final release may perform differently. That single caveat decides how to read the 11-hour coding demos, the 20 benchmark rows, and the November 25 weights promise.
A preview, not a launch: what Baidu shipped on Nov 11
ERNIE 5.5 Flash Preview is an intermediate post-training checkpoint, not a finished model release. Baidu released ERNIE 5.5 Flash Base on November 5, 2026 as a raw pre-training checkpoint (Base announcement), then released the Preview on November 11 as the first post-trained version on that Base, with further improvements planned for the official release.
The model is a sparse mixture-of-experts design with 280 billion total parameters and 14 billion active parameters per token. Context is listed as 1M tokens; endpoint analysis gives precise Qianfan figures of 1,024,000 tokens with 921,600 maximum output. Baidu claims over 200 tokens per second per user on Qianfan (official post).
No Preview repository exists on Hugging Face as of November 11; only ERNIE-5.5-Flash-Base and its BF16 variant from October 21 are there. API behavior, tokenizer, runtime, and pricing today may differ from downloadable weights after November 25.
How to call ERNIE 5.5 Flash Preview today: Qianfan and OpenRouter
ERNIE 5.5 Flash Preview is callable through Baidu Qianfan and OpenRouter. Qianfan lists the formal ID as ernie-5.5-flash-preview under text generation and deep thinking; OpenRouter lists it as baidu/ernie-5.5-flash-preview.
Qianfan's model list (November 10 doc) shows 1M context, input, and output with default limits RPM 60 and TPM 1,000,000. For deep thinking, the 1M output cap includes the thinking chain. The model is text-only under Baidu's description; vision items in Baidu's harness use a Claude Opus 5.5-powered tool (analysis). Reasoning runs at one fixed high-effort level with no off switch (same analysis), so each call pays reasoning tokens.
from openai import OpenAI
# OpenRouter path (verified model ID)
or_client = OpenAI(base_url="https://openrouter.ai/api/v1", api_key="OPENROUTER_KEY")
or_client.chat.completions.create(
    model="baidu/ernie-5.5-flash-preview",
    messages=[{"role": "user", "content": "Summarize this 80-page supplier contract as a table."}],
    max_tokens=4000,
)
# Qianfan path (illustrative; copy base URL + key from Qianfan console, model ernie-5.5-flash-preview)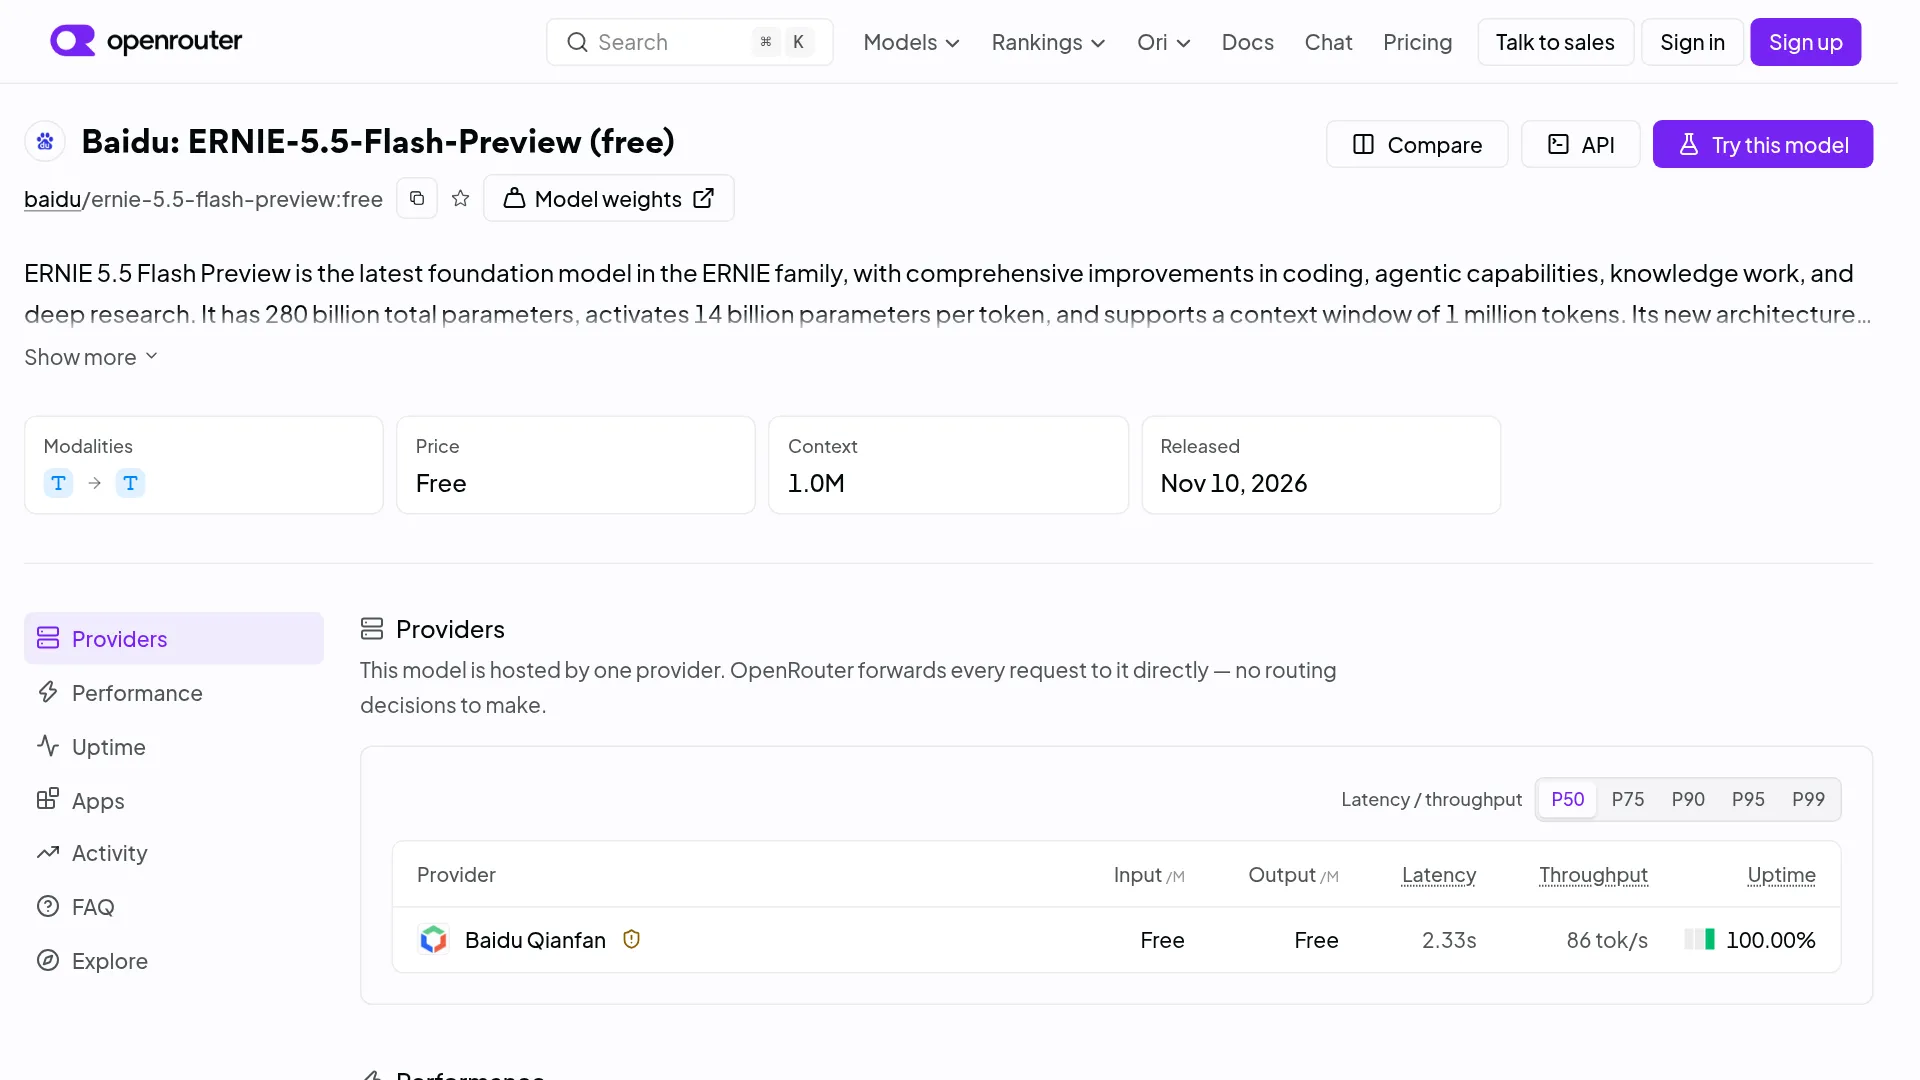
What a long agent run costs on Qianfan and OpenRouter
Qianfan bills pay-as-you-go in yuan per thousand tokens; OpenRouter bills $0.28 input and $1.13 output per million, with $0.028 cached reads. Peak hours (8:00-22:00) list input promo 0.001 / list 0.002, cache 0.0001 / 0.0002, output 0.004 / 0.008 yuan per thousand tokens (Qianfan billing, November 10 doc). Idle hours halve each figure, with no timezone or promo end date stated.
| Path | Input | Output | Cache hit | Notes |
|---|---|---|---|---|
| Qianfan peak promo (8:00-22:00) | 1.00 yuan/M | 4.00 yuan/M | 0.10 yuan/M | Pay-as-you-go, doc 2026-11-10 |
| Qianfan idle promo (22:00-8:00) | 0.50 yuan/M | 2.00 yuan/M | 0.05 yuan/M | Same doc, no timezone stated |
| Qianfan peak list | 2.00 yuan/M | 8.00 yuan/M | 0.20 yuan/M | Non-promo fallback |
| OpenRouter | $0.28/M | $1.13/M | $0.028/M | baidu/ernie-5.5-flash-preview |
Cost formula: input tokens x input rate + (output + reasoning tokens) x output rate. At OpenRouter list, 500K input costs about $0.14 while 500K output-plus-reasoning costs about $0.57. Log reasoning tokens per task before fixing a per-run budget; schedule bulk batches in Qianfan idle hours.
The 20 benchmarks are Baidu's claims, plus four demos and a mid-table ranking
Baidu published 20 benchmark rows and four demonstrations. Each number is Baidu-reported and unreproduced; I found no independent Preview row in Artificial Analysis listings referenced by launch coverage (OrcaRouter, HandyAI). Treat this as a vendor claim sheet, not a leaderboard.
Seven selected rows from Baidu's 20-row table (Baidu-reported unless noted):
| Benchmark | ERNIE 5.5 Flash Preview | Best rival in Baidu's table |
|---|---|---|
| Terminal-Bench 4.0 | 46.5 | Claude Opus 5.5 63.6-66.4 (chart vs table rerun) |
| DeepSWE v1.1 | 71.2 | DeepSeek V4.1 Flash 77.0 |
| AutomationBench | 61.9 | DeepSeek V4.1 Flash 60.5, Hy4 56.2: ERNIE leads |
| SpreadsheetBench V2 | 36.4 | Claude Opus 5.5 35.1, GPT-6.1 Sol 32.0: ERNIE leads |
| OfficeQA Pro V2 | 67.9 | GPT-6.1 Sol 70.0: ERNIE trails by 2.1 |
| APEX-Agents 1.1 | 64.2 | Hy4 77.6, Claude Opus 5.5 73.5: ERNIE trails |
| DRACO | 84.9 | Hy4 90.7, Claude Opus 5.5 87.4: ERNIE mid-pack |
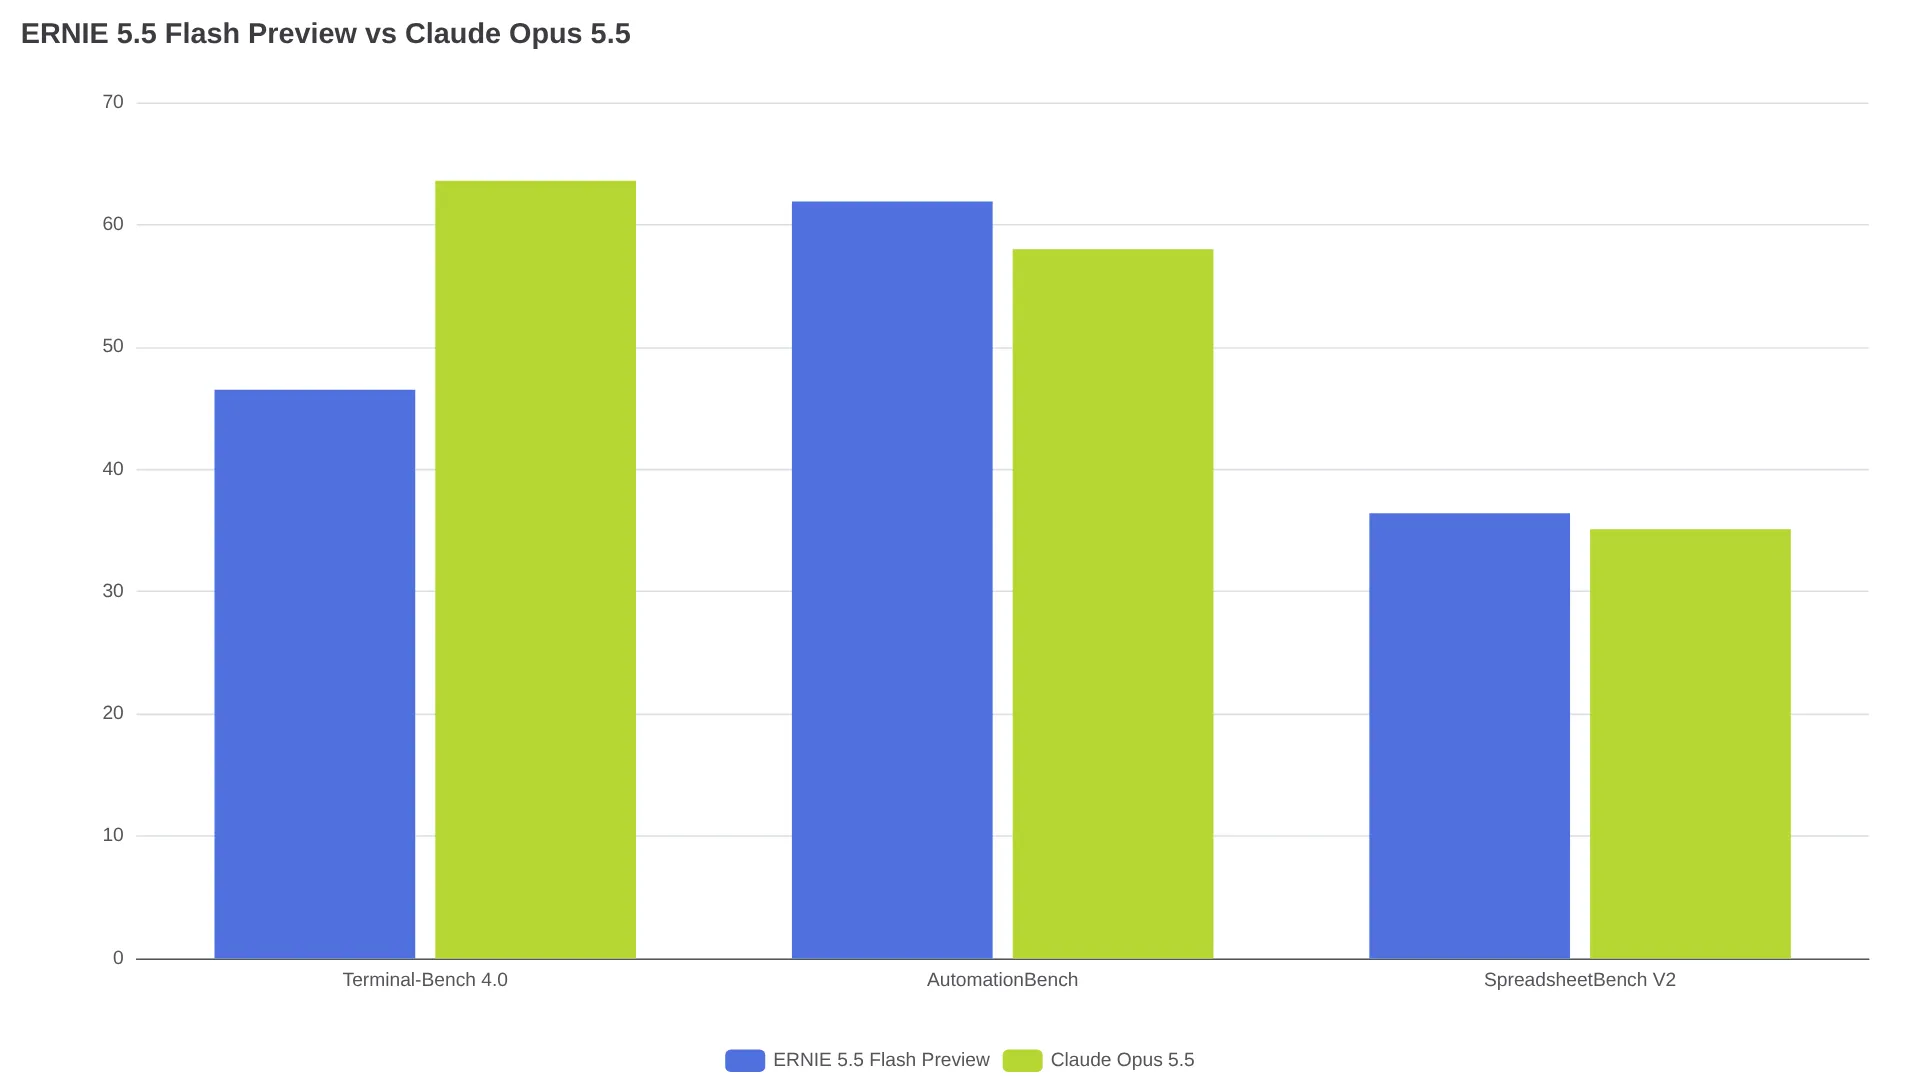
What changes the reading: starred rows are Baidu self-evaluations; the two "AA" rows use Artificial Analysis harnesses but Baidu's own runs (analysis); vision items use a Claude-powered tool; one independent check found Baidu reruns of rivals on AutomationBench ran 15+ points above published numbers (HandyAI); the appendix shipped as an image that blocks auditing.
Baidu's demos claim endurance across four tracks (all figures Baidu-reported): an 11-hour Unreal Engine 5.8 wuxia build plus around 100 mobile mini-games; Blender airport, Horyu-ji complex (about 2,100 objects, 1.82M triangles), and FreeCAD parts; 20- and 24-page research reports, a Monte Carlo workbook, and a 6m34s orchestral WAV; and a 116-second pelican short in 20 styles via 10,000+ lines of Python.
Third-party aggregation puts the Preview mid-pack: Handy AI scored it 67.8 (17th overall) and 69.1 (6th of 57 open-weight), behind Kimi K3.1 Pro (94.4), Hy4 (73.9), and DeepSeek V4.1 Flash 1017 (71.9).
"Baidu's new model isn't the headline. The license is. ... If Apache 2.0 happens, that's a real change." — @thestonyground, X post
Weights, license, and local runs: the November 25 promise with a wording split
The weights are promised, not published. The English announcement says Apache 2.0 soon; the Chinese announcement says before November 25 with no license named.
Flash Base shipped under a restricted license excluding the EU, UK, and South Korea with attribution requirements (repo, analysis). Teams in those regions should wait for Preview terms in writing.
I found no GGUF, quantization table, or official VRAM figure for the Preview. Active parameters do not equal resident memory: 280B parameters at 4 bits is roughly 140GB before overhead, so any 32GB-VRAM setup implies heavy CPU offload. The r/LocalLLaMA thread offers only a rough community estimate near 32GB VRAM + 128GB RAM, with doubts that 200 tokens/second reflects consumer batch-1 speed. Do not buy hardware before November 25.
Should you build on the Preview this week
Try the Preview for cheap long-context pilots; wait for the final release for anything load-bearing. First workloads worth piloting on Baidu's unreproduced numbers: spreadsheet edits, office-file QA, and automation batches.
| Situation | Move |
|---|---|
| Spreadsheet / OfficeQA / AutomationBench-style batches | Try the API now; idle-hour Qianfan or OpenRouter keeps tests cheap |
| 1M-context reads and research synthesis | Pilot with strict output budgets; mandatory reasoning inflates runs |
| Terminal coding as primary dependency | Stay on Opus / GPT / DeepSeek; retest after independent reruns |
| EU / UK / KR production or self-host | Wait for the repository and a named Apache 2.0 license |
| Fine-tune or distill | Wait; confirm training terms in the Preview license |
Baidu's demos claim endurance, but verifiability is missing: use the Preview as a low-cost second model for long agent runs until independent rows and a dated Apache 2.0 repository land.
Is ERNIE 5.5 Flash Preview open source yet?
No. API access is live, but weights were not public on Hugging Face on November 11. Publication is promised by November 25, with Apache 2.0 named only in English.
Is ERNIE 5.5 Flash Preview multimodal?
No, it is text-only. Demos orchestrate external tools through code; vision benchmark items use a Claude-powered tool.
What is the difference between Flash Base, Flash Preview, and the final Flash?
Base (November 5) is a raw checkpoint; Preview (November 11) is the first post-trained intermediate version; the final Flash is the forthcoming official release.
Why does the Terminal-Bench gap to Claude Opus 5.5 matter?
The gap suggests lower reliability on long terminal tasks; because reasoning is mandatory, retries may also raise cost. ERNIE scored 46.5 versus 63.6-66.4 for Opus 5.5.
Is the Preview safe for production use?
No independent rerun existed at launch and behavior may change. Pilot non-critical batches; gate production on reruns plus the final license.