 AIREITER
Anthropic's new flagship lists at $8 input and $40 output per million tokens, yet task cost spans $2.48 to $44.70 by effort. For Claude Fable 5.2, effort routing decides the invoice.
Claude Fable 5.2 API pricing: IDs, cache, Batch, Fast mode
Official pricing is $8.00 input, $40.00 output, $0.20 cache reads, $10.00 five-minute writes, and $16.00 one-hour writes per million tokens. Model ID claude-fable-5-2 (Claude Platform Docs), Bedrock bedrock/claude_platform/claude-fable-5-2 (LiteLLM). Context 1M tokens, max output 128K, minimum cacheable prompt 512 tokens. Batch halves live rates to $4.00/$20.00; Fast doubles them to $16.00/$80.00 for up to 2.5x speed. Cost formula: input x $8 + output x $40, minus cache hits at $0.20, halved on Batch.
| Item | Fable 5.2 | Fable 5.1 | Opus 5.5 |
|---|---|---|---|
| Input / 1M | $8.00 | $10.00 | $4.00 |
| Output / 1M | $40.00 | $50.00 | $20.00 |
| Cache read / 1M | $0.20 | $0.25 | $0.20 |
| Cache write 5-min / 1M | $10.00 | $12.50 | $5.00 |
| Cache write 1-hr / 1M | $16.00 | $20.00 | $8.00 |
| Batch input / output | $4.00 / $20.00 | $5.00 / $25.00 | $2.00 / $10.00 |
| Fast input / output | $16.00 / $80.00 | n/a | $8.00 / $40.00 |
| Context / max output | 1M / 128K | 1M / 128K | 1M / 128K |
The like-for-like math: 10M input plus 1M output costs $150 on Fable 5.1, $120 on Fable 5.2 standard ($240 Fast), $60 on Opus 5.5. Cache breaks even after about two prefix reuses: writes cost 1.25x input while reads cost 2.5% of input. One modeled medium workload (20M input, 5M output, 80% cached) falls $360 to $235, a $125 saving.
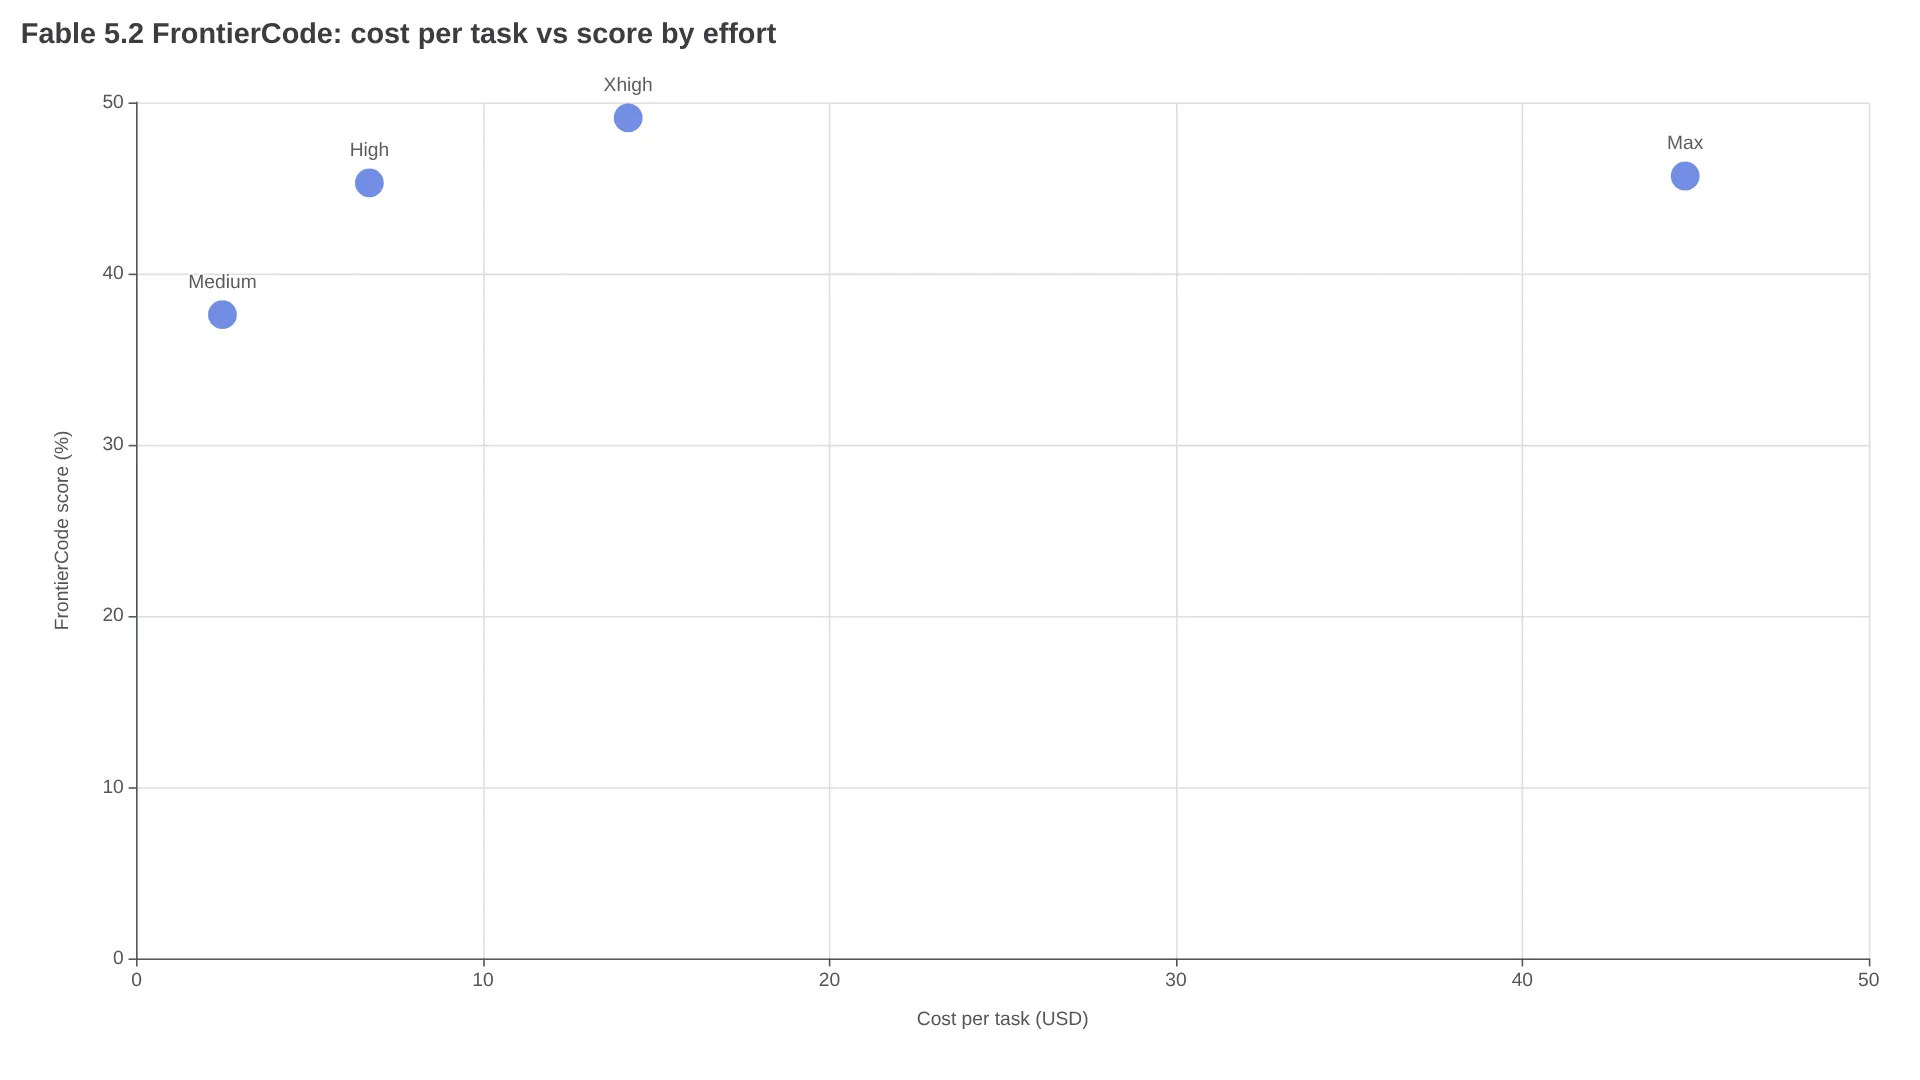
Effort economics: $2.48 to $44.70 on the same model
Independent reporting on Cognition's FrontierCode 2.0 (132 merge-ready patch tasks) puts Fable 5.2 at $2.48 per task at Medium (37.6%), $6.72 at High (45.3%), $14.19 at Xhigh (49.1%), and $44.70 at Max (45.7%). Medium is the default in Claude apps and Code per that reporting. Max costs 3.15x Xhigh while scoring lower, so fixed Max routing wastes budget on this suite.
| Signal | Fable 5.2 | Rival | Read |
|---|---|---|---|
| FrontierCode, equal spend | High 45.3% at $6.72 | GPT-6 Astra Max 42.8% at $6.68 | Fable +2.5 pts at parity |
| FrontierCode peak | Xhigh 49.1% at $14.19 | Opus 5.5 Max 45.5% at $12.82 | Fable peak costs more, scores more |
| Generation jump | 49.1% Xhigh | Fable 5.1 Xhigh 32.4% at $8.68 | +16.7 pts at +63% task cost |
Per the same reporting, Fable 5.2 Medium beats Fable 5.1 Xhigh by 5.2 points at roughly 71% lower task cost ($2.48 vs $8.68). Agent totals move more than rates: tests, re-reads, retries, and delegation shift spend beyond the 20% list cut. Default to High for hard tasks, escalate to Xhigh only behind a quality gate, and keep Max off unless a benchmark on your own workload justifies it.
Fable 5.2 vs Opus 5.5: routing by task price
Anthropic's launch guidance, per the official announcement, recommends Opus 5.5 for most coding and knowledge work and reserves Fable 5.2 for unusually difficult tasks, as advisor to cheaper models or orchestrator delegating to faster ones. Fable lists at $8/$40 versus Opus at $4/$20, so routine work on Fable pays double for capability it does not need.
| Workload | Pick | Cost logic |
|---|---|---|
| Stuck migration, persistent bug, hard design | Fable 5.2 High | $6.72 task cost halves Opus Max $12.82 at equal score |
| Peak score, budget secondary | Fable 5.2 Xhigh | 49.1% at $14.19 |
| Routine code, docs, drafts | Opus 5.5 | Half token price, vendor default |
| Repeated system prompts | Fable High + caching | 512-token minimum; 5-min vs 1-hr write tradeoff |
| Latency-bound session | Test Fast ($16/$80) vs High | Pay double only if throughput wins |
| Offline backfill | Batch API | 50% cut: Fable $4/$20, Opus $2/$10 |
Quota burn and resets: what subscriptions don't show (user reports)
Launch-week quota reports are user reports, not documented API policy. Claude Code and Pro users describe rapid 5-hour and weekly consumption plus uncertainty over whether a Fable reset restores 5-hour allowance, weekly Fable allowance, or general capacity. Anthropic's announcement describes one to three Fable resets during the launch promotion by subscription history.
"ate through 20% of my weekly in about 10 minutes" — u/travisrd, r/claude “Fable 5.2. is INSANE”
"absolutely chewing through my 5-hour limit!!" — u/myairblaster, r/ClaudeAI “Fable 5.2”
"caught a bunch of bugs and a few critical ones opus 5.5 missed" — u/TheMagicalOppai, r/ClaudeAI “Fable 5.2”
Spiky bug hunts suit pay-as-you-go API keys because 5-hour caps bind subscriptions while API spend scales per High-effort task (about $6.72 each in the FrontierCode sample). Confirm reset scope in-app before routing team work to Fable, and track 5-hour versus weekly meters separately.
Fable vs Mythos: same weights, different gate
Fable 5.2 and Mythos 5.2 share weights with different safeguards per the official announcement. Fable is generally available with 55% fewer mistaken refusals than 5.1. Mythos removes cyber and biology blocks for vetted organizations via the Cyber and Life Sciences Verification Programs, and bills at the same $8/$40 token rates.
Fable availability covers paid Claude plans, Claude Code, Claude Platform API, AWS, Google Cloud, and Microsoft Azure from November 9, 2026, with up to 30% faster generation than 5.1.
Teams weighing cheaper defaults can check Claude Sonnet 5.5 API review and pricing for the $2/$10 path.