 AIREITER
GPT-5.6 Sol consumed 16.45 million tokens per session across 1,715 Codex sessions, 2.25x the 7.30 million tokens GPT-5.5 averaged over a comparable 1,667-session window. Same per-token price, more than double the tokens. On top of that, a documented defect in the Responses API appears to inflate billed output_tokens by 6x or more for Sol. If your GPT-5.6 bill looks wrong, it probably is.
How Many Tokens GPT-5.6 Sol Actually Uses
Developer Vincent Schmalbach tracked token consumption across two 14-day windows of Codex usage, comparing GPT-5.5 xhigh against GPT-5.6 Sol xhigh with near-identical session counts:
| Metric | GPT-5.5 xhigh | GPT-5.6 Sol xhigh |
|---|---|---|
| Sessions | 1,667 | 1,715 |
| Total tokens | 12.17B | 28.22B |
| Tokens per session | 7.30M | 16.45M |
Session count rose 2.9%. Tokens per session rose 125%. Total consumption jumped from 12.17 billion to 28.22 billion, a 2.32x increase for roughly the same workload.
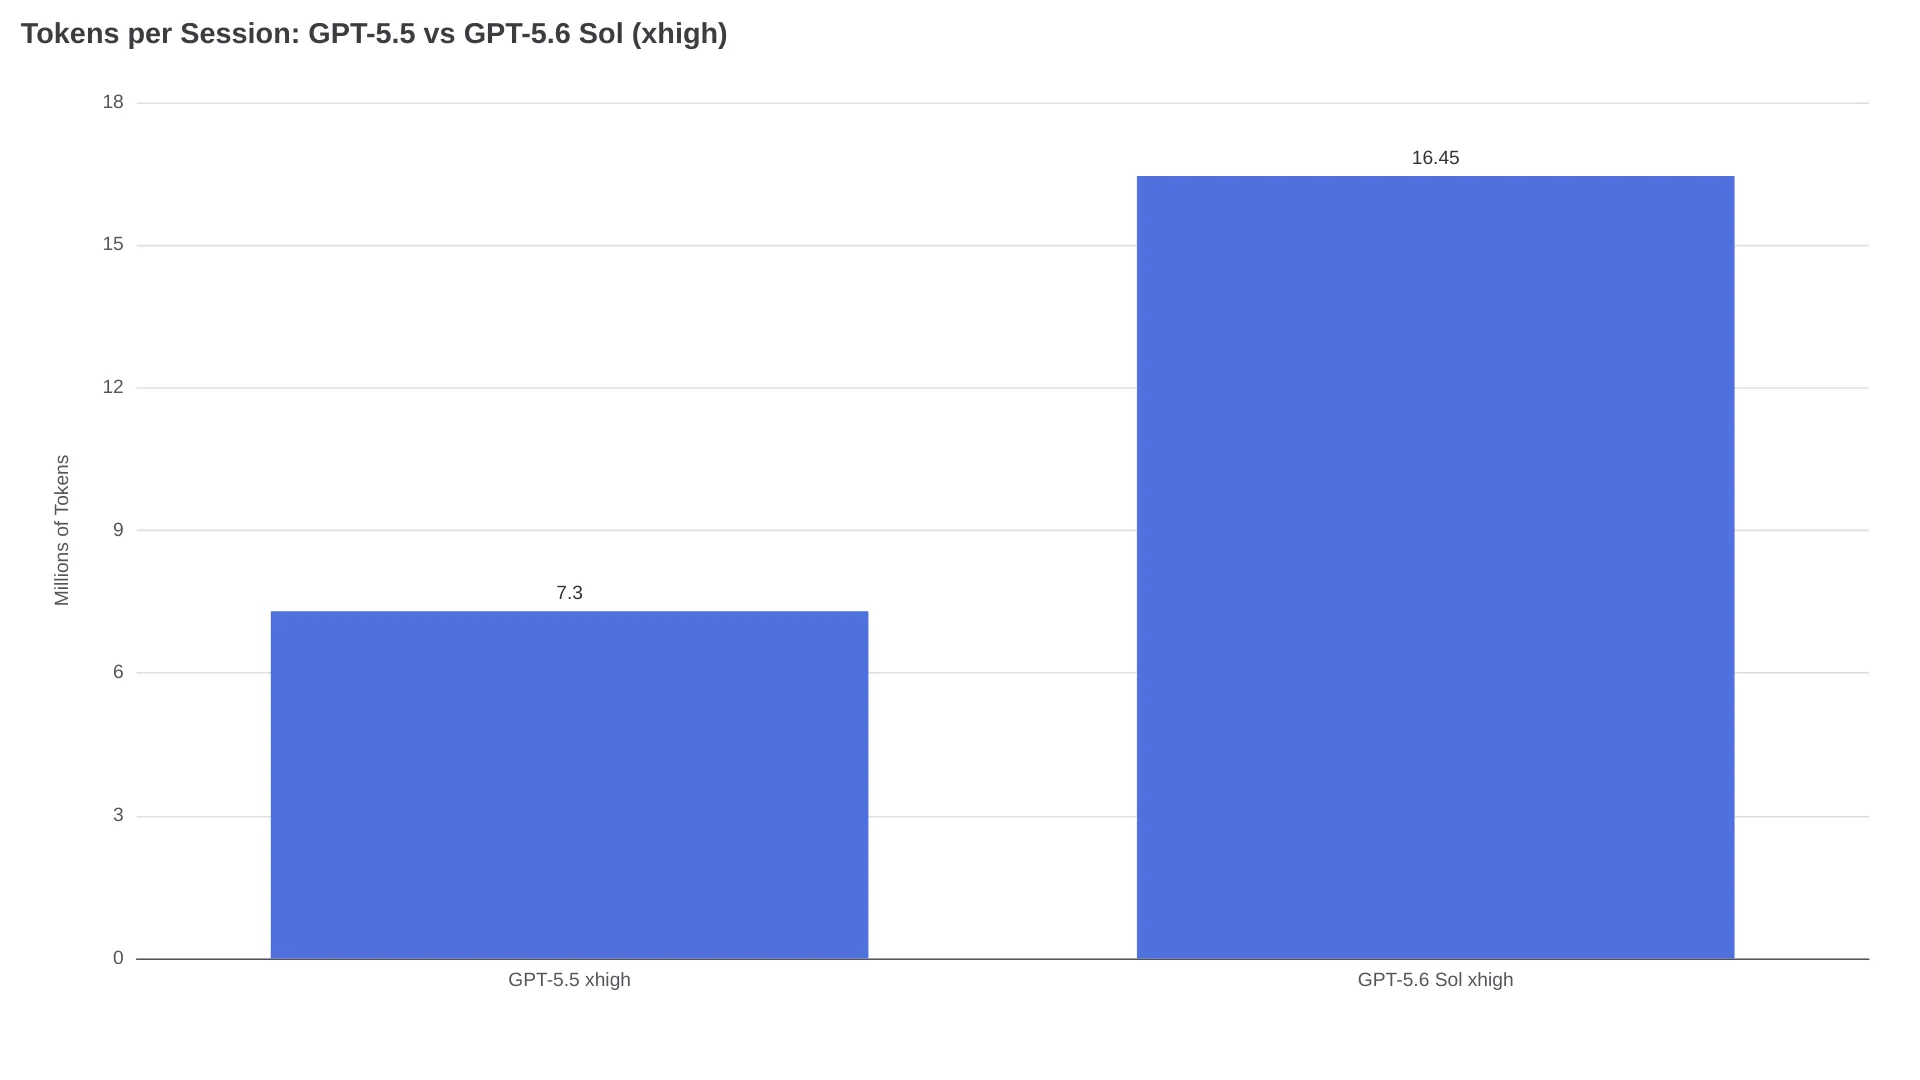
OpenAI's pricing page lists GPT-5.6 Sol at $5/1M input and $30/1M output, identical to GPT-5.5. At the same rate, 2.25x the tokens means roughly 2.25x the cost per task. GPT-5.6 Sol also introduced a cache-write surcharge (1.25x the input rate) that GPT-5.5 did not have.
"GPT 5.6 Sol is a token furnace. Even Sol on medium or high seems to gobble tokens. 5.6 will only be used for complex planning or tricky bugs." — r/codex user
Schmalbach's three subscriptions, which previously lasted a week of heavy work, now drain in about one day of medium usage.
Why Sol Uses More Tokens
Sol is more efficient per benchmark point than competitors. On the Artificial Analysis Coding Agent Index, it uses fewer output tokens than Claude Fable 5 for equivalent scores. But in real sessions, Sol reasons more aggressively: it plans, backtracks, validates, and explores alternatives. The trade-off is higher token burn per task, even though each token does more useful work.
A Reported Billing Defect That Inflates Output Token Counts
Beyond higher real usage, a documented accounting defect in the Responses API appears to inflate the output_tokens field, and billing is computed from it. OpenAI is investigating but has not publicly confirmed the root cause.
A developer documented the issue across 710 GPT-5.6 calls and 22,922 total reasoning calls. GPT-5.6 is the first model family to emit multiple reasoning items per response (median k=9 for Sol, k=4 for Terra). An accumulator in the API adds the running reasoning total once per reasoning item during generation, on top of the correct final count.
The formula:
output_tokens ≈ R × (k + 3) / 2Where R is the actual reasoning tokens and k is the number of reasoning items. For Sol with a median k=9, this inflates the billed count by roughly 6x. For Terra with k=4, roughly 3.6x.
What This Looks Like on a Real Bill
The worst documented example: a single GPT-5.6 Terra call that returned a four-character answer (d1d4) was billed for 466,818 output tokens against only 21,064 actual reasoning tokens.
| What the API reported | Value |
|---|---|
output_tokens (billed) | 466,818 |
reasoning_tokens (actual) | 21,064 |
| Visible output | d1d4 (4 characters) |
| Reasoning items (k) | 41 |
With k=41, the formula predicts R × (41+3)/2 = 21,064 × 22 = 463,408, within 0.7% of the billed amount. The reporter verified this against their billing dashboard: summing the API's output_tokens and applying published rates reproduced dashboard charges to the tenth of a cent. Across their GPT-5.6 calls, ~$284 of ~$320 billed was overcharge.
This Bug Predates GPT-5.6
At k=1 (one reasoning item, which is what pre-5.6 models emit), the formula reduces to R × 4/2 = 2R, a flat 2x overcharge. The reporter confirmed this against OpenAI's own usage export for May 2026:
| Model | Billed output tokens | True count | Ratio |
|---|---|---|---|
| o3-mini | 25,408,973 | 12,376,132 | 2.02x |
| gpt-5.4-nano | 11,718,610 | 5,844,140 | 2.00x |
| o1 | 778,989 | 335,944 | 2.01x |
| o4-mini (control) | 12,054,680 | 9,160,567 | 1.01x |
GPT-5.6 did not introduce the defect. It is the first model to chunk reasoning into many items, which turns a quiet 2x into a much larger multiplier. The reason: reasoning is emitted in ~512-token chunks, so k ≈ ceil(R/512). Substituting into the formula gives output_tokens ≈ R²/1024 + 3R/2, meaning the overcharge grows quadratically with reasoning length. Double the thinking, roughly quadruple the bill.
As of this writing (August 2026), OpenAI staff have responded to the bug report requesting additional data, but no fix or billing adjustment has been confirmed publicly.
Current GPT-5.6 Pricing After the July 30 Cut
On July 30, 2026, OpenAI reduced Luna's price by 80% and Terra's by 20%. Sol's pricing remained unchanged. Current rates from OpenAI's pricing page:
| Model | Input (short) | Cached input | Cache writes | Output (short) | Output (long) |
|---|---|---|---|---|---|
| GPT-5.6 Sol | $5.00 | $0.50 | $6.25 | $30.00 | $45.00 |
| GPT-5.6 Terra | $2.00 | $0.20 | $2.50 | $12.00 | $18.00 |
| GPT-5.6 Luna | $0.20 | $0.02 | $0.25 | $1.20 | $1.80 |
| GPT-5.5 | $5.00 | $0.50 | — | $30.00 | $45.00 |
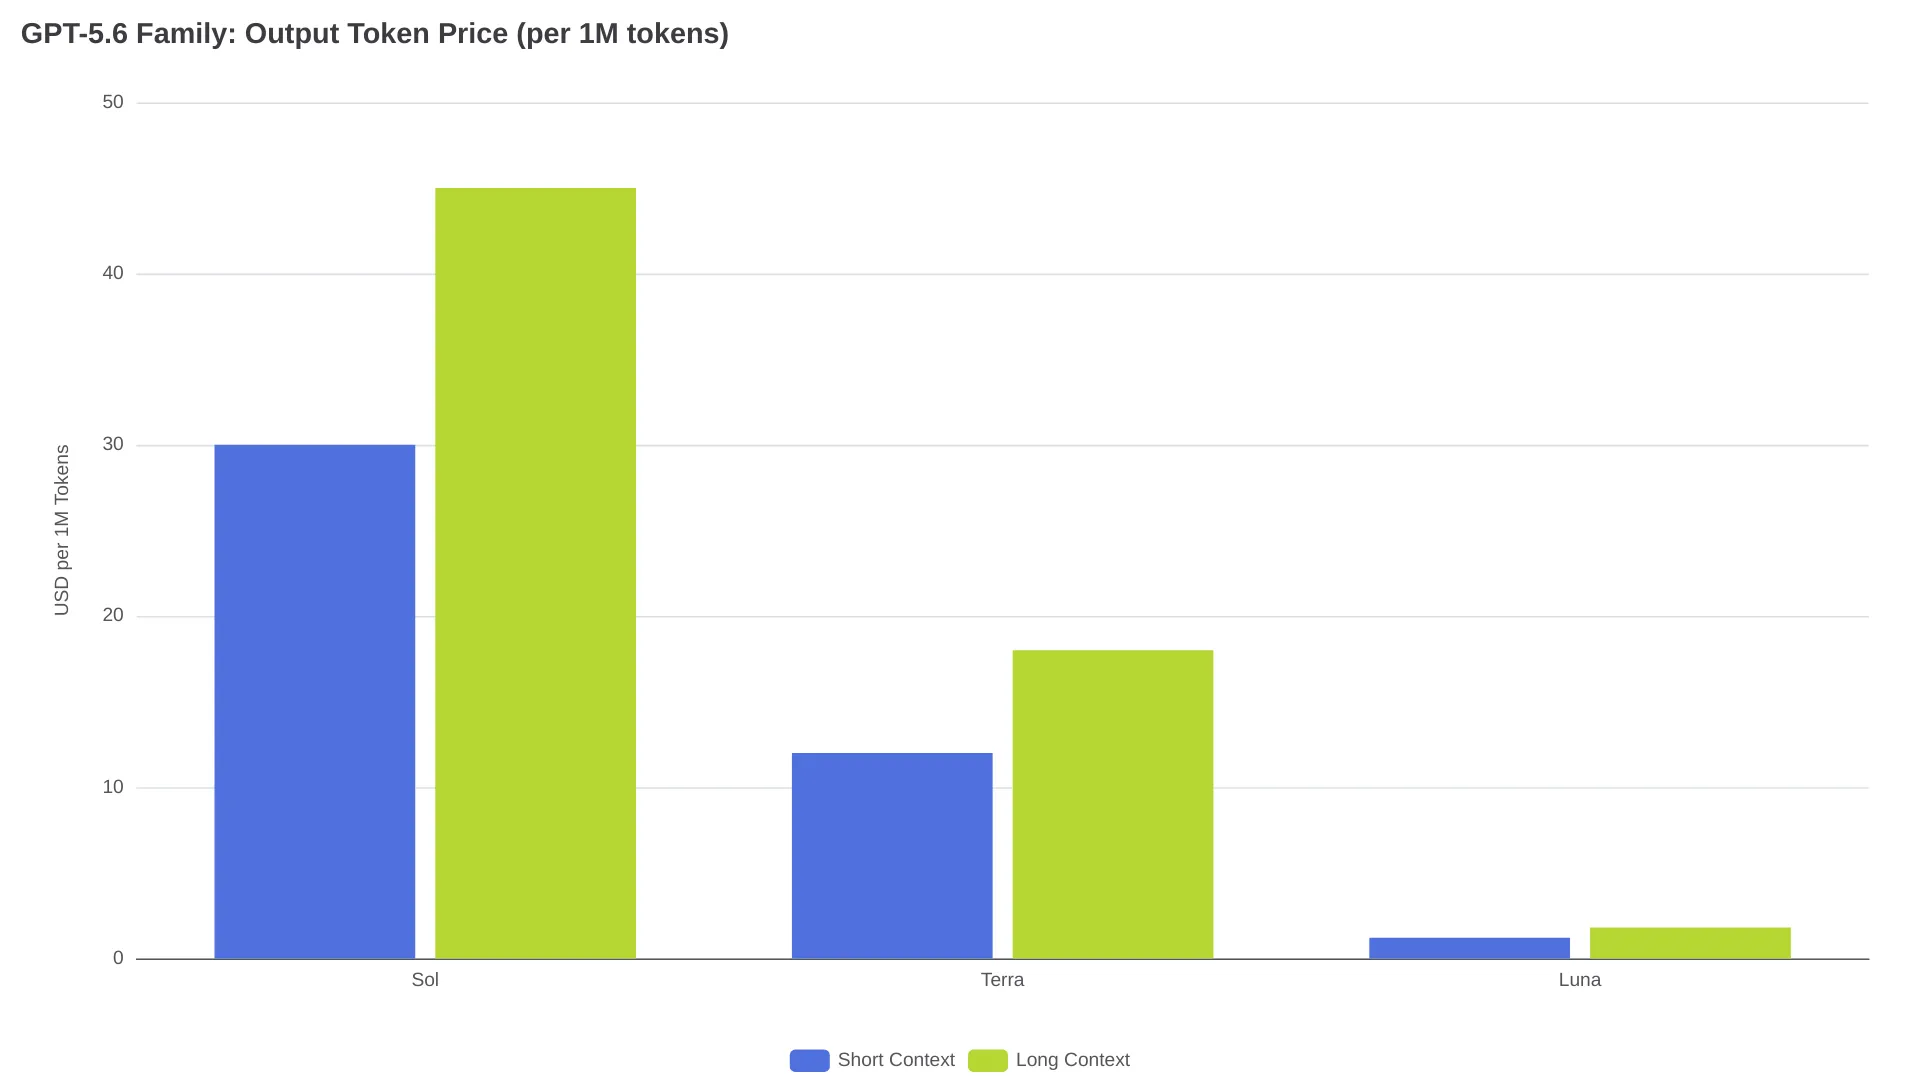
Sol costs the same per-token as GPT-5.5 but uses 2.25x the tokens per task, so your effective per-task cost roughly doubles.
Cache writes are a new line item. GPT-5.6 charges 1.25x the input rate for cache writes ($6.25/1M for Sol). GPT-5.5 had no cache-write fee. If your workload has a low cache-hit rate, this adds a 25% surcharge on top of your input costs that did not exist before.
Luna now undercuts GPT-5.4 nano. At $0.20/$1.20 versus nano's $0.20/$1.25, post-cut Luna is the cheapest model in OpenAI's lineup.
Three Ways to Cut Your GPT-5.6 Token Bill
Drop to Terra for Routine Tasks
Terra's output rate is $12/1M, 60% less than Sol's $30/1M. On the Artificial Analysis Coding Agent Index, Terra scores just above Claude Fable 5. After the July 20% price cut, Terra at $2.00/$12.00 also undercuts the old GPT-5.5 rate.
When does Sol still make sense? Multi-step debugging sessions, architecture planning across large codebases, security analysis. Those tasks benefit from extended reasoning chains. For standard coding, analysis, and content generation, Terra delivers comparable results at a fraction of the token burn.
Use Lower Effort Settings
The reasoning.effort parameter controls how many reasoning tokens the model generates, and the reported billing defect scales directly with reasoning items (k). At medium, Sol emits fewer reasoning items than at xhigh, so the billing inflation drops proportionally.
"I use Terra Ultra and the token usage actually seems much more efficient than GPT 5.5." — r/codex user
The token-furnace behavior concentrates in Sol at high effort levels. Setting reasoning.effort to medium or high instead of xhigh or max is the single highest-leverage change you can make.
Maximize Cache Hits
GPT-5.6 introduced explicit cache breakpoints and a 30-minute minimum cache life. Cache reads get a 90% discount, dropping Sol's input cost from $5.00 to $0.50 per 1M. Cache writes, however, cost 1.25x the input rate ($6.25/1M for Sol).
Structure your prompts so the system message and static context sit before a cache breakpoint. The break-even depends on your specific workload: cache-write premium is 25% of the input rate, while cache-read savings are 90%, so you need a hit rate where savings on reads outweigh the write surcharge. For workloads where most requests share a long system prompt, this tips in your favor quickly.
FAQ
Has OpenAI acknowledged the billing defect?
An OpenAI staff member (Mark G.) responded to the community forum report on July 12, 2026, requesting request IDs and timestamps for investigation. No fix or retroactive billing adjustment has been publicly confirmed as of August 2026.
How do I check if the billing defect affects my account?
For any response with multiple reasoning items, add usage.output_tokens_details.reasoning_tokens plus the visible completion tokens. If usage.output_tokens exceeds that sum by more than a few percent, the cumulative re-summing behavior documented in the forum report is likely affecting your bill. Download your usage CSV from the OpenAI dashboard and check by model.
Should I switch from Sol to Terra?
For most API workloads, Terra costs less and scores competitively on coding benchmarks. Sol's edge shows on the hardest tasks: OpenAI's own benchmarks show Sol outperforms Terra most on multi-step reasoning and security research, where extended thinking time has the highest payoff.